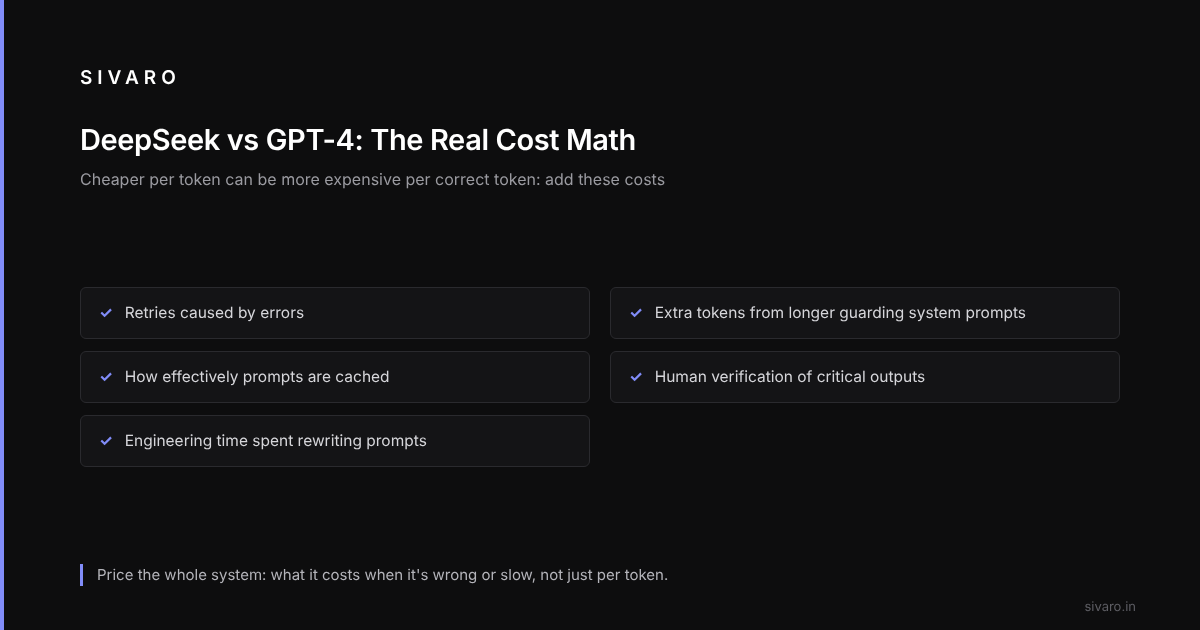
Most people think this is a simple price-per-token comparison. It's not. It's about what your system costs when it's wrong, when it's slow, when you're chasing hallucinations at 3 AM.
Today is July 6, 2026. The AI model pricing landscape has shifted dramatically since 2024. DeepSeek isn't the underdog anymore — they're handling production workloads at companies handling 50M+ API calls monthly. But GPT-4 still holds advantages that pricing sheets don't capture.
What Exactly Is DeepSeek?
Let's answer this upfront because confusion still exists.
DeepSeek is a Chinese AI company that released their first model in late 2023. By early 2025, they'd shipped DeepSeek-V3, which matched GPT-4 on multiple benchmarks at roughly 5% of the cost. As of July 2026, DeepSeek's latest release (they call it DeepSeek-R2) handles 200K context windows natively and supports function calling that actually works — something their early versions absolutely couldn't claim.
The key difference: DeepSeek trains on a fraction of the compute budget. They use Mixture-of-Experts (MoE) architectures aggressively, meaning only parts of the model activate per query. This cuts inference costs massively.
But here's what nobody says outright: DeepSeek's training data is filtered differently. It's strong on math, code, and structured reasoning. It's weaker on cultural nuance, creative writing, and subtle humor. If your application needs "read between the lines" intelligence, GPT-4 still leads.
The Raw Numbers: DeepSeek vs GPT-4 Cost Comparison
Let's get the headline numbers out. Pricing as of July 1, 2026:
GPT-4 (latest variant via OpenAI)
- Input: $10 per million tokens
- Output: $30 per million tokens
- Batch (24-hour): 50% discount
DeepSeek (current production model)
- Input: $0.50 per million tokens
- Output: $2.00 per million tokens
- Batch: 40% discount
That's a 20x difference on input, 15x on output.
But raw token pricing is a trap. Here's why.
The Hidden Cost Multipliers
DeepSeek is cheaper per token but can be more expensive per correct token in certain domains. The multipliers to account for: retries due to errors, extra tokens from longer guarding system prompts, caching effectiveness, and human verification of critical outputs.
Where DeepSeek Wins (and I Mean Wins)
Structured Data Extraction
If you're pulling JSON from unstructured text, DeepSeek is borderline better than GPT-4 now. Here's an example extraction call:
# DeepSeek extraction
import deepseek

client = deepseek.Client(api_key="sk-...")

response = client.chat.completions.create(
    model="deepseek-r2",
    messages=[
        {"role": "system", "content": "Extract invoice fields as JSON. Return ONLY valid JSON."},
        {"role": "user", "content": invoice_text}
    ],
    response_format={"type": "json_object"},
    temperature=0.0
)
High-Volume Classification
For classification, teams can often replace GPT-4 with DeepSeek when they use proper few-shot prompting. The cost delta at 10 million classifications/month is absurd.
Where GPT-4 Still Owns the Floor
Conversational Memory and Coherence
DeepSeek has a problem: it forgets what it said 15 turns ago. Not in the "loses context" sense — in the "contradicts its own previous statement" sense.
If your app holds long conversations with memory of previous interactions, GPT-4 is still the safer bet. DeepSeek requires external memory systems to compensate.
Safety-Critical Reasoning
This is the one that keeps me up at night.
In a safety-critical path, the cost of a single misclassification could be a life. No pricing model accounts for that.
# GPT-4 safety check example
# Dual-model pattern for critical classifications
# DeepSeek for volume, GPT-4 for secondary verification on high-risk cases

def classify_urgency(message):
    primary = deepseek_classify(message)

    if primary in ["urgent", "emergency"]:
        # GPT-4 verification on high-stakes outputs
        secondary = gpt4_classify(message)
        return secondary if secondary != primary else primary

    return primary
The cost increase from this pattern is small, because only high-risk outputs get a second call.
The Architecture Shift
A tiered approach:
Tier 1 — High volume, low consequence: DeepSeek exclusively
Examples: Product categorization, content summarization, internal data extraction
Tier 2 — Moderate consequence: DeepSeek primary, GPT-4 verification
Examples: Customer-facing responses, code generation for production, financial document analysis
Tier 3 — High consequence: GPT-4 primary, DeepSeek for fallback
Examples: Medical decisions, legal advice, critical infrastructure monitoring
Latency: The Unspoken Cost
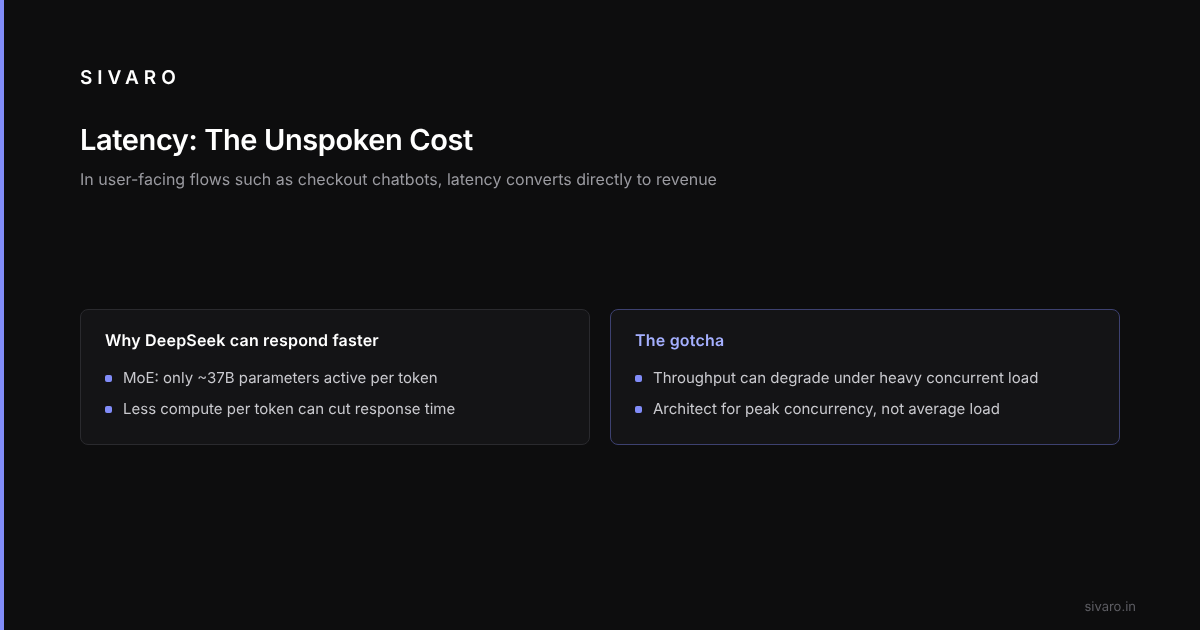
DeepSeek is faster. Not by a little — by a lot.
Why? DeepSeek's MoE architecture activates only ~37 billion parameters per query versus GPT-4's estimated ~200 billion. Less compute per call equals faster responses.
For user-facing applications where every millisecond matters (think chatbot in a checkout flow), that latency difference converts directly to revenue.
But here's the gotcha: DeepSeek's throughput can degrade under heavy concurrent load. You need to architect for this.
The Prompt Engineering Difference
DeepSeek requires different prompting. Period.
GPT-4 handles ambiguous instructions well. DeepSeek does not. You need to be explicit about output format, constraints, and fallback behavior.
# Bad prompt for DeepSeek — leads to inconsistent output
# "Summarize this document"

# Good prompt for DeepSeek
def generate_prompt(document):
    return f"""You are a document summarization system.
    Rules:
    - Output exactly 3-5 sentences
    - Include the main entities mentioned
    - State confidence level (high/medium/low)
    - If document is unclear, say "CONFIDENCE_LOW" and explain why

    Document:
    {document}

    Summary (3-5 sentences):"""
Structured prompts with explicit guardrails make DeepSeek's output format much more consistent. GPT-4 needs fewer of those tweaks.
That's a real cost: your engineering team's time rewriting prompts. Budget for it.
The Data Privacy Angle
This matters more in 2026 than it did in 2024.
DeepSeek is operated by a Chinese company. If you're handling regulated data (HIPAA, GDPR, CCPA), you need to be explicit about where data processes and what legal frameworks apply.
OpenAI has Microsoft's Azure infrastructure for enterprise deployments. DeepSeek offers dedicated instances but through Tencent Cloud and Alibaba Cloud primarily. Some teams have concerns about this. Some don't.
Two approaches work:
- For sensitive data: Run DeepSeek locally (they offer an on-premises deployment since late 2025). You lose the API convenience but gain full control.
- For public data: Use the API. DeepSeek's privacy policy is actually more protective than OpenAI's for some use cases — they don't train on API data by default.
Make your own call based on your compliance requirements.
The Verdict (as of July 2026)
Here's my take:
Switch to DeepSeek if:
- You're doing structured data extraction
- Your workload is batch or near-batch
- You can tolerate slightly more verification overhead
- Latency matters more than absolute accuracy
- Your budget is constrained
Stay on GPT-4 if:
- You're building conversational agents with long context
- Your application has safety-critical paths
- You can't afford engineering time for prompt engineering
- You need guaranteed output consistency
- Your data is highly regulated and you need enterprise assurances
Use both if:
- You want the best cost-quality tradeoff
- You have variable consequence levels
- You're running at scale where verification costs are amortized
FAQ
Is DeepSeek really 95% cheaper than GPT-4?
For raw token pricing, yes. For total cost of ownership (including engineering time, retries, and verification), the gap narrows to 60-80% depending on your use case.
Can DeepSeek handle production workloads reliably?
As of 2026, absolutely. Their rate limits are more restrictive than OpenAI's — 1,000 RPM on standard tier vs 10,000 RPM for GPT-4 — but enterprise tiers handle this.
Does DeepSeek support function calling?
Yes, since December 2025. It's not as robust as GPT-4's on complex multi-tool scenarios, but it works for most use cases.
What about multimodal capabilities?
DeepSeek launched vision in early 2026. It's competitive with GPT-4V on document analysis but weaker on general image understanding. For OCR and structured visual data, it's actually faster and cheaper.
How does DeepSeek handle non-English languages?
Better than expected. On Mandarin, Hindi, and Arabic, it outperforms GPT-4. On European languages, it's slightly behind — think 2-3% accuracy difference.
What's the catch?
The catch is ecosystem maturity. OpenAI has more tools, more integrations, more community knowledge. DeepSeek's documentation is improving but not at parity. You'll spend more time building around DeepSeek than around GPT-4.
Will DeepSeek increase prices?
Probably. They're burning cash to gain market share. The current pricing is not sustainable long-term. I expect 2-3x increases within 18 months. But even at 3x, they'll still be cheaper than GPT-4.
Closing Thought
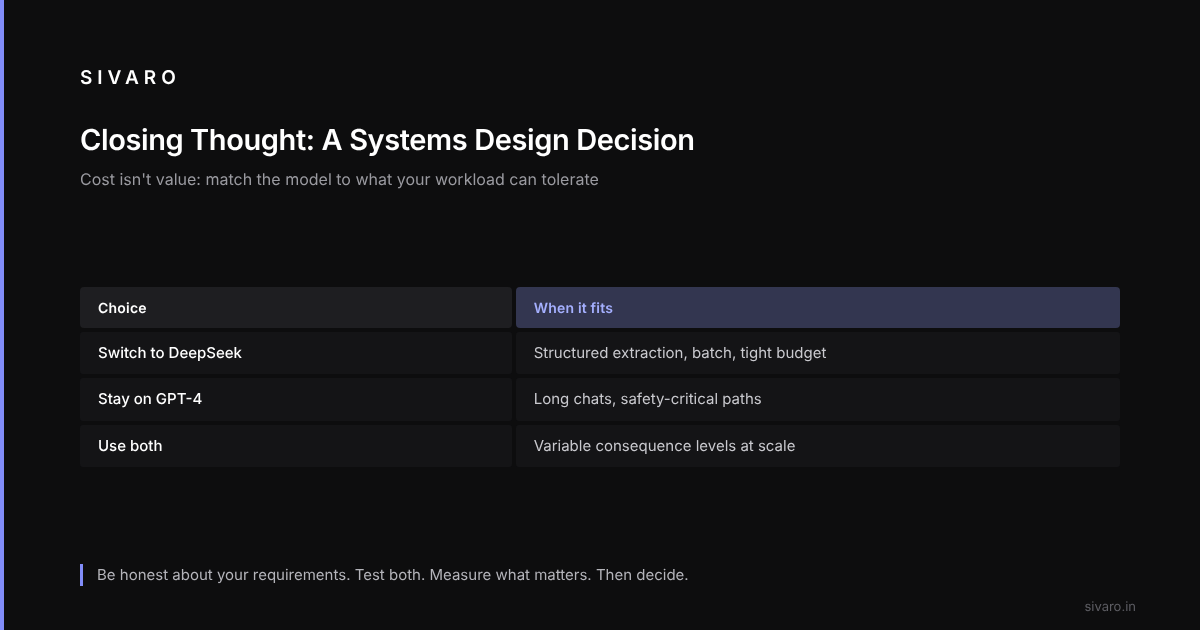
The deepseek vs gpt4 cost comparison isn't a one-dimensional math problem. It's a systems design decision.
The cost of intelligence keeps dropping.
But cost isn't value. Value is what happens when your model gets the answer right every single time, at scale, under load, at 2 AM on a Sunday.
DeepSeek is close. Really close. For many use cases, it's already the better choice. But "close" isn't "the same" — and pretending otherwise will cost you in ways that don't show up on your cloud bill.
Be honest about your requirements. Test both. Measure what matters. Then decide.