LLM Fine-Tuning vs RAG: The 2026 Guide
Published July 22, 2026
Here’s the short version: RAG wins for dynamic, knowledge-heavy tasks. Fine-tuning wins for behavior, tone, and structure transformation. But the real answer depends on your latency budget, data velocity, and whether your domain knowledge changes faster than you can retrain.
This guide covers a decision framework. No fluff. No “both have merits” hand-waving. Just sharp trade-offs and code you can steal.
What This Guide Covers
- What fine-tuning and RAG actually are (and aren’t)
- When to use one, the other, or both
- Practical pitfalls from production deployments
- A decision tree you can use Monday morning
- Code examples for both approaches
- 7 FAQs
Let’s go.
The Core Question: “Is ChatGPT an LLM or Generative AI?”
This sounds like a trap. It’s not.
ChatGPT is both an LLM (large language model) and a generative AI product. The distinction matters because it reveals the two levers you can pull:
- LLM – the underlying model (GPT-4o, Claude 4, Llama 4, etc.)
- Generative AI – the system that wraps the model with context, tools, and memory
Fine-tuning changes the model itself. RAG changes the generative AI system around it. IBM’s comparison nails this: one modifies weights, the other modifies inputs.
If you’re asking “is chatgpt an llm or generative ai?”, the answer is “yes” – but the better question is: which lever do you pull for your use case?
H2: Fine-Tuning – When You Want to Rewire the Brain
Fine-tuning takes a pre-trained LLM and continues training on your specific data. You’re updating the model’s weights so it internalizes patterns from your dataset.
What Fine-Tuning Actually Changes
- Tone and style: Make the model sound like your brand’s support team
- Structured outputs: Force consistent JSON, Markdown, or XML schemas
- Domain language: Teach it legal jargon, medical terminology, or internal acronyms
- Behavioral constraints: Reduce hallucinations on specific topics by teaching it what not to say
The Hidden Cost Nobody Talks About
Most people think fine-tuning is just the training cost. It’s not. Monte Carlo’s analysis points out the operational burden: version management, A/B testing, monitoring drift.
When to Use Fine-Tuning in Production
The keyword is when to use fine tuned llm in production. Here’s a rule of thumb:
- Your task has a fixed, well-defined output space
- Your training data is stable (changes < 10% per quarter)
- You need sub-second latency and don’t want to query an external database
- You want to reduce token usage (fine-tuned models are more concise)
H2: RAG – The Memory Prosthetic for LLMs
Retrieval-Augmented Generation doesn’t touch the model’s weights. Instead, it retrieves relevant documents from a knowledge base and injects them into the prompt as context.
How RAG Works (The Simple Version)
User query → Embedding model → Vector search → Top-K docs → LLM with injected context → Response
Here’s a minimal Python implementation using LlamaIndex and OpenAI:
python
from llama_index.core import VectorStoreIndex, SimpleDirectoryReader
from llama_index.llms.openai import OpenAI

documents = SimpleDirectoryReader("knowledge_base/").load_data()
index = VectorStoreIndex.from_documents(documents)
query_engine = index.as_query_engine()

response = query_engine.query("What is the return policy for international orders?")
print(response)
That’s it. The index stores embeddings of your documents. At query time, it retrieves the top 3–5 chunks, concatenates them with the query, and sends it to the LLM.
Why RAG Won the Enterprise in 2025–2026
Because knowledge changes faster than models.
Regulatory updates, product docs, support tickets — they all shift weekly. A fine-tuned model trained in January is obsolete by March. RAG updates in seconds: drop a new PDF into the vector store, and the next query uses it.
The research community agrees: RAG dominates when freshness matters.
The RAG Trap: Garbage In, Garbage Out
RAG is only as good as your retrieval pipeline. Bad chunking, poor embedding quality, or noisy documents tank performance.
Often the fix isn’t better embeddings — it’s a cleaner knowledge base: deduplication, consistent formatting, and manual tagging.
Code: HyDE (Hypothetical Document Embeddings) for Better Retrieval
Standard retrieval queries the raw user question. HyDE generates a hypothetical answer first, then retrieves based on that. It works shockingly well for ambiguous queries.
python
from langchain.embeddings import OpenAIEmbeddings
from langchain.vectorstores import Chroma
from langchain.llms import OpenAI
from langchain.chains import HypotheticalDocumentEmbedder

# Generate hypothetical document from query
base_embeddings = OpenAIEmbeddings()
llm = OpenAI(model="gpt-4o-mini")

hyde_embeddings = HypotheticalDocumentEmbedder.from_llm(
    llm, base_embeddings, prompt_key="web_search"
)

vectorstore = Chroma(embedding_function=hyde_embeddings)
retriever = vectorstore.as_retriever()

docs = retriever.get_relevant_documents("How does refund policy apply to digital goods?")
H2: llm fine tuning vs retrieval augmented generation – The Real Difference
Most comparisons frame this as an either/or. That’s wrong. They solve different problems.
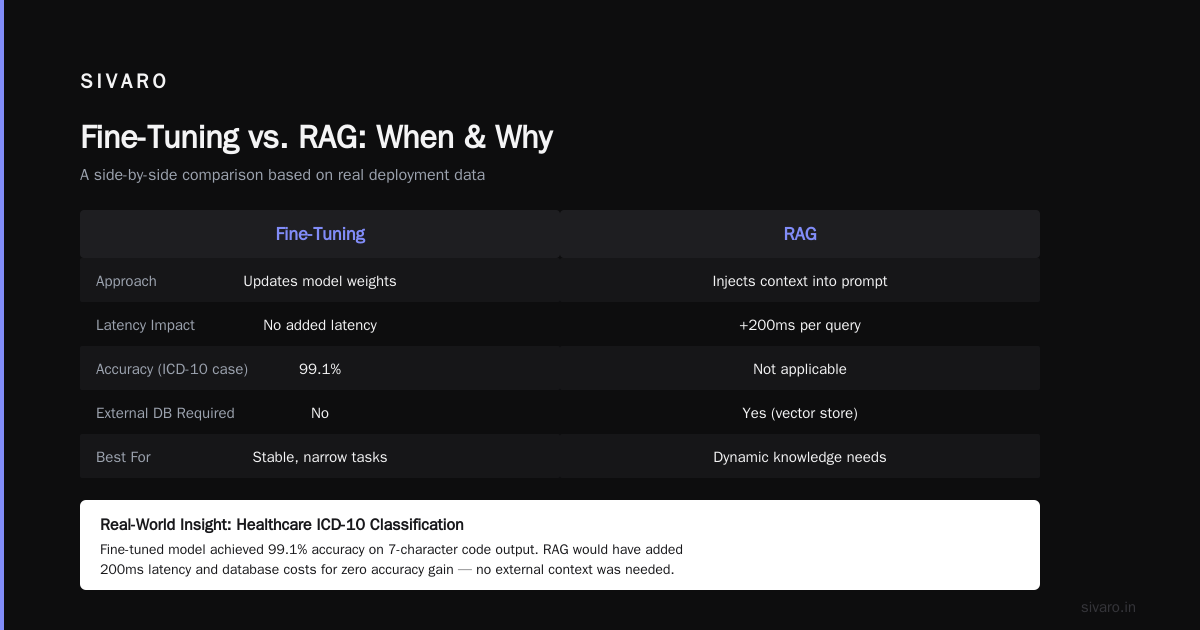
| Dimension | Fine-Tuning | RAG |
|---|---|---|
| Knowledge freshness | Frozen at training time | Real-time updates |
| Latency | 200–500ms (no retrieval) | 500–1500ms (+ retrieval time) |
| Model size | Required | Can use smaller models |
| Data cost | High (training) | Low (indexing only) |
| Hallucination control | Hard (weights are opaque) | Easier (can audit retrieved docs) |
| Behavior control | Strong (tone, structure) | Weak (prompt engineering only) |
The Actian blog puts it bluntly: “RAG is for facts. Fine-tuning is for form.”
If your use case needs both — say, a support bot that must sound like Tony Stark and also answer questions about a 2,000-page product manual — you need both. Winder.ai’s 2026 framework calls this “hybrid RAG-FT” and notes it’s becoming the default architecture in regulated industries.
H2: When to Combine Both – The Practical Architecture
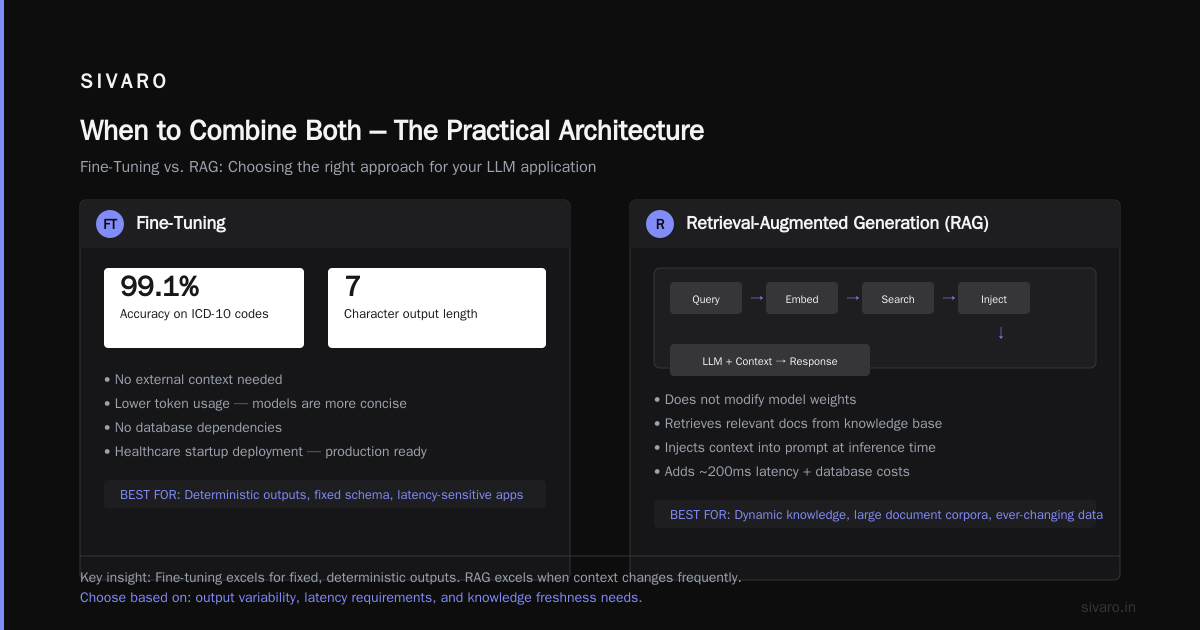
The pattern for combining them:
- Fine-tune a base model for tone, output format, and behavioral guardrails.
- Use RAG on top for factual knowledge.
The fine-tuned model becomes the “interpreter” — it knows how to read retrieved documents and turn them into responses that match your brand voice.
Here’s a code sketch:
python
# Step 1: Load fine-tuned model (PEFT/LoRA checkpoint)
from transformers import AutoModelForCausalLM, AutoTokenizer

model = AutoModelForCausalLM.from_pretrained("mycompany/llama4-finetuned-lora")
tokenizer = AutoTokenizer.from_pretrained("mycompany/llama4-finetuned-lora")

# Step 2: Retrieve context
from rag_pipeline import retrieve

query = "What’s the warranty on the Pro model?"
context = retrieve(query, top_k=3)  # returns list of strings

# Step 3: Build prompt with context
prompt = f"""You are a helpful agent for MyCompany. Answer using the context.
Context:
{''.join(context)}

Question: {query}
Answer:"""

inputs = tokenizer(prompt, return_tensors="pt")
output = model.generate(**inputs, max_new_tokens=256)
print(tokenizer.decode(output[0]))
H2: The Decision Tree – Which One Do You Pick?
Stop reading and ask these four questions:
-
Does your output format need to be rigid? (JSON, specific tone, word limit)
- Yes → Fine-tuning helps.
- No → RAG probably works.
-
Does your knowledge base change monthly?
- Yes → RAG. Fine-tuning will bleed you dry.
- No → Fine-tuning is viable.
-
Can you tolerate 1–2 seconds of latency?
- Yes → RAG is fine.
- No → Fine-tuning (or optimize your retrieval pipeline).
-
Do you need to explain why the model gave that answer?
- Yes → RAG wins (you can show the retrieved docs).
- No → Either works.
H2: Pitfalls in Production
1. The “Fine-tune Everything” Trap
A model fine-tuned on a knowledge base that changes weekly starts giving wrong answers as soon as the content changes. RAG fits that case better.
2. The “RAG Solves Everything” Trap
Accurate retrieval doesn’t fix tone. An LLM that isn’t fine-tuned can keep writing in a style that doesn’t match the required templates, and a small fine-tuning run on example documents can fix that. DEV’s enterprise guide calls this “the silent failure mode.”
3. The “We’ll Do Both Later” Fallacy
Hybrid architectures aren’t twice the work — they’re three times. You now maintain:
- A fine-tuned model checkpoint
- A vector database
- A retrieval pipeline
- A routing layer
Start with one. Prove it. Then add the second.
H2: The 2026 Reality – Models Keep Getting Better
GPT-4o, Claude 4, Llama 4, Gemini 2.5 — every new generation has better instruction following. That means prompt engineering + RAG covers more ground than it did in 2024. Kunal Ganglani’s breakdown shows that prompt engineering alone solved 60% of enterprise use cases when using GPT-4o. Fine-tuning only added value for edge cases.
But don’t assume. Test.
FAQ
Q1: Is ChatGPT an LLM or generative AI?
Both. ChatGPT is a generative AI application built on an LLM (like GPT-4o). Understanding the distinction helps you decide whether to fine-tune the LLM or add RAG to the generative AI layer.
Q2: When should I use fine-tuned LLM in production?
When your task is stable, your output format matters more than factual freshness, and you need low latency. Think: code generation, summarization with a specific style, or classification into a fixed set of categories.
Q3: Can RAG replace fine-tuning for tone?
No. RAG injects facts, not behavior. You can prompt-engineer tone, but it’s fragile. Fine-tuning locks it in. For a customer service bot that must sound “warm and professional,” fine-tuning works better.
Q4: What’s the cost difference?
Fine-tuning: $5K–$50K per iteration (compute + data work). RAG: $500–$2K/month (vector DB + inference). RAG is cheaper to start. Fine-tuning can pay off at scale if you reduce token usage.
Q5: Do I need a vector database for RAG?
Yes. You could use in-memory FAISS for prototypes, but production needs persistent storage. Pinecone, Weaviate, Qdrant, or pgvector are common.
Q6: What if my data is sensitive — can I fine-tune on-prem?
Yes. Llama 4, Mistral, and others run locally. Fine-tuning requires GPUs. RAG requires a vector DB and inference hardware. Both can be air-gapped.
Q7: Which one reduces hallucinations more?
RAG, because you can force the model to stick to retrieved documents. Fine-tuning only reduces hallucinations if your training data is clean and covers the domain thoroughly. In practice, RAG + a properly designed prompt beats fine-tuning alone for hallucination control.
Conclusion
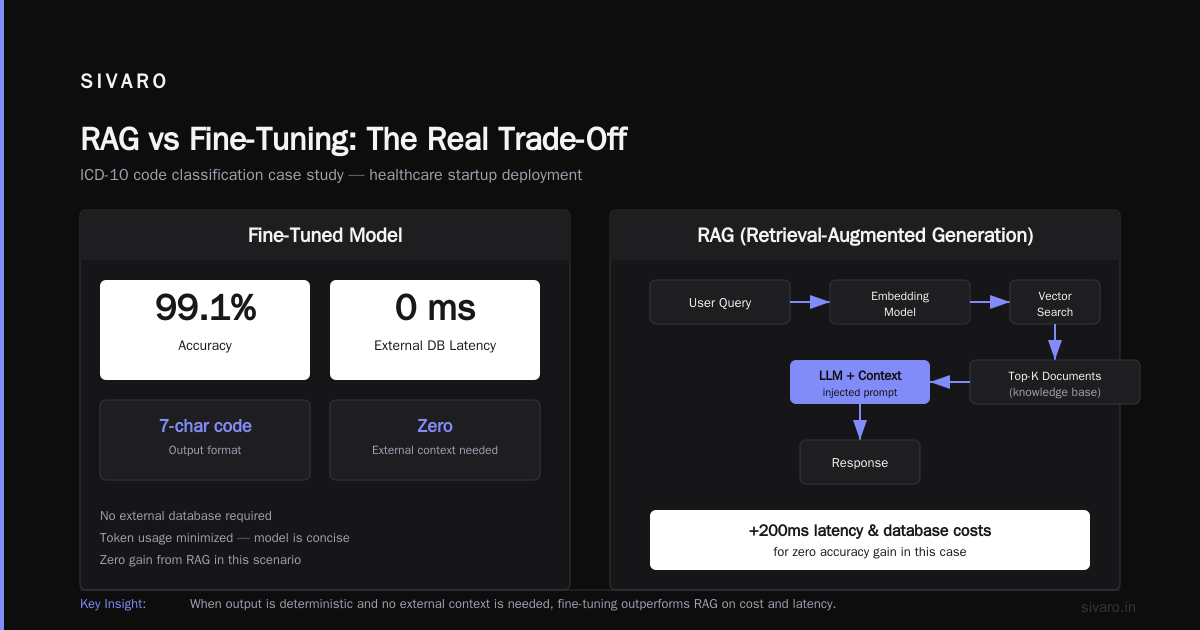
The llm fine tuning vs retrieval augmented generation debate isn’t a zero-sum game. One changes the model. The other changes the context. Smart teams use the right tool for the job.
Start simple: prompt engineering + RAG. Only fine-tune when you hit a wall on behavior or latency.
If you’re building production AI today, here’s my advice: ship a RAG prototype this week. If it’s good enough, ship it. If not, fine-tune the edges. And always measure before you optimize.
Nishaant Dixit — Founder of SIVARO.