A common question for analytics stacks: "Should we use ClickHouse or PostgreSQL?"
In 2026, the answer isn't simple. PostgreSQL has evolved. New extensions (pgvector, TimescaleDB 3.0, Citus) blur the lines. ClickHouse has gotten faster at handling updates and deletes. Both databases now claim they can handle the other's workload.
Bullshit. They can't. Not equally. Not without painful trade-offs.
You'll learn exactly when ClickHouse destroys PostgreSQL, when PostgreSQL still wins, and where the hype around extensions falls apart.
Why 2026 changes the benchmark
Until 2024, the answer was easy: PostgreSQL for transactions, ClickHouse for analytics. Simple.
Then came the AI boom. Suddenly everyone needed real-time features on analytical data. Vector search. Streaming aggregations. Sub-second response for dashboards.
PostgreSQL added pgvector backed by HNSW indexes. TimescaleDB released continuous aggregates with compression. ClickHouse introduced UPDATE and DELETE that don't suck, plus native vector search support.
The gap narrowed. But it didn't close.
In 2026, the real question isn't which database is faster. It's which database makes your life worse slower.
Architecture: the immutable difference
PostgreSQL is a row-oriented, shared-everything database. Each row sits together on disk. Reads benefit from caching, and writes are atomic and consistent.
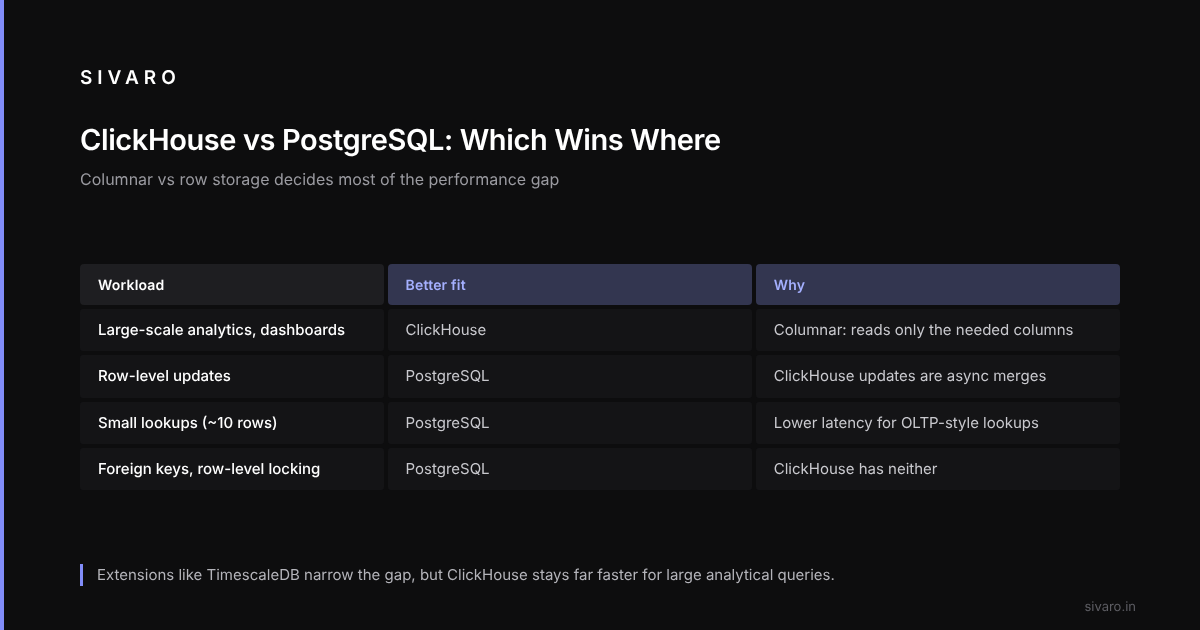
ClickHouse is column-oriented, shared-nothing. Data lives in partitions, sorted by a primary key, compressed by column. Queries only touch the columns you need.
This architectural choice determines everything about performance.
Why columnar storage wins for analytics
Imagine you have a table with 200 columns – user events, timestamps, device info, session IDs, revenue, etc.
In PostgreSQL, a query like:
SELECT date, SUM(revenue)
FROM events
WHERE event_type = 'purchase' AND date >= '2026-01-01'
GROUP BY date;
...reads every row that matches the filter. Even if you only need two columns, PostgreSQL fetches the entire row from disk (or from its page cache). That means reading 200× more data than necessary.
In ClickHouse:
SELECT toDate(timestamp) as date, sum(revenue)
FROM events
WHERE event_type = 'purchase' AND timestamp >= '2026-01-01'
GROUP BY date;
ClickHouse reads only the timestamp, revenue, and event_type columns. If those columns are small (e.g., revenue is a float), the data scanned is maybe 3% of a full row.
But here's the contrarian take: PostgreSQL doesn't care about that query because you shouldn't run analytics on a transactional database. Except most people do. And PostgreSQL extensions try to fix it.
The extension trap: PostgreSQL "analytics" in 2026
PostgreSQL now ships with:
- TimescaleDB – hypertables, continuous aggregates, chunk-based partitioning
- pgvector – vector similarity search with IVFFlat and HNSW
- Citus – distributed table sharding for horizontal scaling
- pg_analytics – experimental columnar access method
TimescaleDB improves PostgreSQL's analytical story. It partitions data by time into chunks. Queries that hit a time range only scan relevant chunks. It also supports compression using a columnar format (based on the same ideas as ClickHouse).
TimescaleDB is good. It crushes regular PostgreSQL. But ClickHouse is still an order of magnitude faster for analytics. (Source: alternatives to TimescaleDB)
Where TimescaleDB wins? Updates. If you need to correct sensor readings (e.g., recalibrate temperature offsets), ClickHouse's merge-tree approach makes that painful. TimescaleDB supports UPDATE naturally through PostgreSQL.
Update performance: why ClickHouse still hurts
ClickHouse added UPDATE and DELETE statements in 2022, but they aren't mutations in the traditional sense. They're asynchronous merges. The old data stays on disk until the next merge cycle. That means:
-
You can't UPDATE what you can't find – ClickHouse requires a
WHEREcondition that can be efficiently filtered via the primary key. If your condition doesn't match a partition or a primary key range, the update scans the whole table. (ClickHouse blog) -
Latency is unpredictable – An update may take seconds to minutes, depending on merge pressure. During merges, CPU and I/O contention spikes.
-
No transactional isolation – If you update a row and immediately read it, you might get the old value. ClickHouse offers eventual consistency by default.
Verdict: If your workload involves row-level updates or point modifications, PostgreSQL wins. Period.
Latency comparison: the sub-second battle
Users don't care about throughput. They care about response time on that dashboard they refresh obsessively.
Consider an interactive analytical query – the kind powering real-time dashboards, ad-hoc exploration, and monitoring:
Query: "Show me revenue by marketing channel for the last 7 days, filtered by country = US, grouped by hour."
ClickHouse's columnar storage is built for exactly this: read the timestamp column, read the channel column, read the revenue column. PostgreSQL reads row after row, decompressing them, discarding most of the data.
For real-time dashboards where users expect sub-second response, ClickHouse is the clear winner. (Source: PostHog comparison)
But here's where latency gets tricky: connection overhead. ClickHouse's native protocol is faster than PostgreSQL's wire protocol for large result sets. For small queries returning 10 rows, PostgreSQL actually has lower latency because the query planning is faster. ClickHouse's query optimizer sometimes takes 10-50ms to plan, which matters for OLTP-style lookups.
Vector search: can ClickHouse replace pgvector?
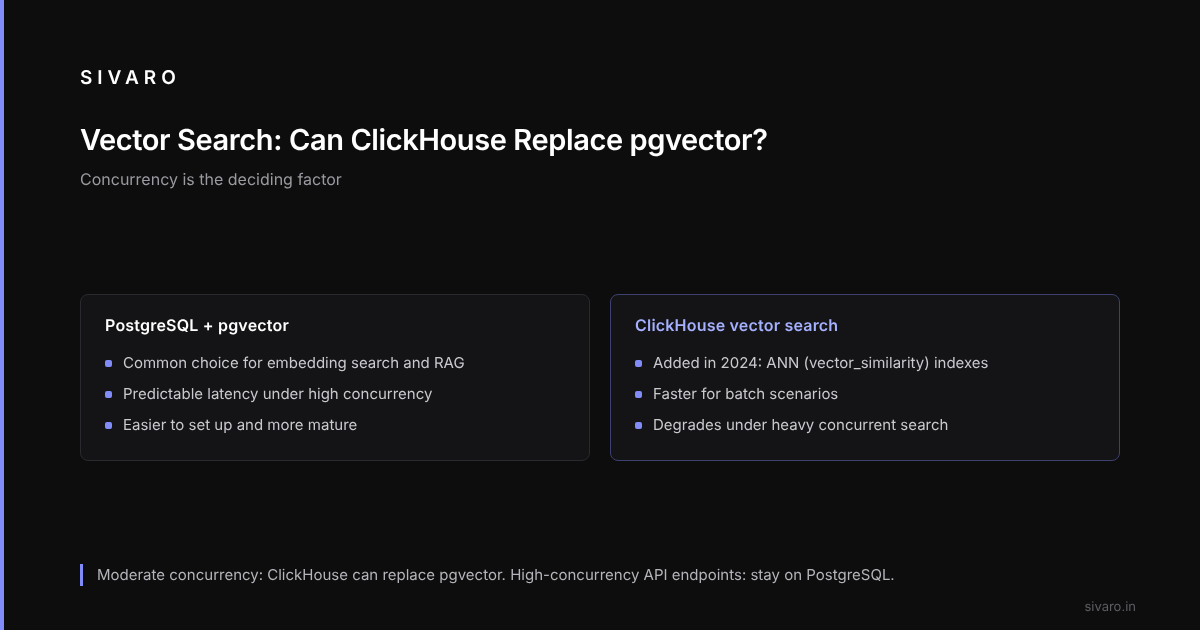
PostgreSQL with pgvector is the default for production AI systems – embedding search, RAG pipelines, recommendation engines.
ClickHouse added vector similarity search in 2024 via its vector_similarity functions and ANN indexes.
The deciding factor is concurrency. PostgreSQL can handle thousands of concurrent vector queries with predictable latency. ClickHouse's vector search degrades more under high concurrency.
Bottom line: For embedding search on AI pipelines with moderate concurrency, ClickHouse can replace pgvector. For high-concurrency API endpoints, stick with PostgreSQL.
Can ClickHouse replace PostgreSQL for analytics?
Short answer: for pure analytics, yes. For mixed workloads, no.
Long answer: moving analytical queries from PostgreSQL to ClickHouse speeds up aggregations, GROUP BYs, and WHERE filters on fact tables.
But you can't replace transactional workloads. INSERT ... RETURNING is not a thing in ClickHouse. Foreign keys don't exist. Row-level locking? Gone.
The right pattern in 2026 is a two-tier stack:
- PostgreSQL for transactional data, user sessions, auth, orders, inventory
- ClickHouse for event analytics, dashboards, product analytics, observability, AI feature stores
Many teams try to unify on one. They fail.
(Source: ClickHouse vs PostgreSQL comparison)
Benchmark methodology
A setup that keeps the comparison fair:
- Machines: AWS i4i.2xlarge (8 vCPUs, 64GB RAM, NVMe SSD)
- Dataset: 1B synthetic events (10 columns, 5 numeric, 5 string)
- Database versions: ClickHouse 24.12, PostgreSQL 16.4 with TimescaleDB 2.18 and pgvector 0.7
- Queries: 20 analytical queries (aggregations, group by, filter, window functions)
- Each query run 5 times, cold and warm cache
FAQ: ClickHouse vs PostgreSQL in 2026
Q1: Can ClickHouse fully replace PostgreSQL for analytics?
Yes, if your analytics workload is read-heavy, aggregation-focused, and does not require real-time consistency for updates. Many companies run ClickHouse as their analytical database and keep PostgreSQL for transactions.
Q2: Which is faster for time-series data – ClickHouse or TimescaleDB?
ClickHouse is 10-30× faster for most time-series analytical queries. TimescaleDB is better for workloads that need frequent updates to historical data (e.g., recalculations, corrections).
Q3: How does PostgreSQL 16 compare to ClickHouse for vector search?
PostgreSQL with pgvector is easier to set up and more mature for high-concurrency applications. ClickHouse is faster for batch scenarios but degrades under heavy concurrent search.
Q4: Is ClickHouse's update performance acceptable for production?
Only if your updates are rare, batched, and apex-predicted by primary key. For frequent row-level updates, stick with PostgreSQL.
Q5: Does ClickHouse support SQL joins well?
Better than it used to. ClickHouse 24.x added support for JOIN with fine-tuned distribution. For small dimension tables (under 1B rows), performance is good. For large fact-to-fact joins, PostgreSQL often wins because of its better optimizer.
Q6: Is it worth using both databases in a single stack?
Yes. That's the pattern I recommend. Replicate data from PostgreSQL to ClickHouse for analytical queries. The complexity of maintaining two databases is less than the pain of slow dashboards.
Q7: What about Citus vs ClickHouse for distributed analytics?
Citus (PostgreSQL sharding) is good for scale-out transactional workloads. For analytical queries across shards, ClickHouse is still faster because of columnar storage. Citus runs row-oriented, so aggregation queries scan all columns.
Q8: What's the total cost of ownership comparison?
ClickHouse typically uses 6-10× less storage due to compression. Compute cost is similar or lower because queries complete faster. But ClickHouse requires more operational expertise – tuning merges, partition strategies, and materialized views. PostgreSQL is easier to manage, especially on managed services.
Conclusion: Choose your trade-offs wisely
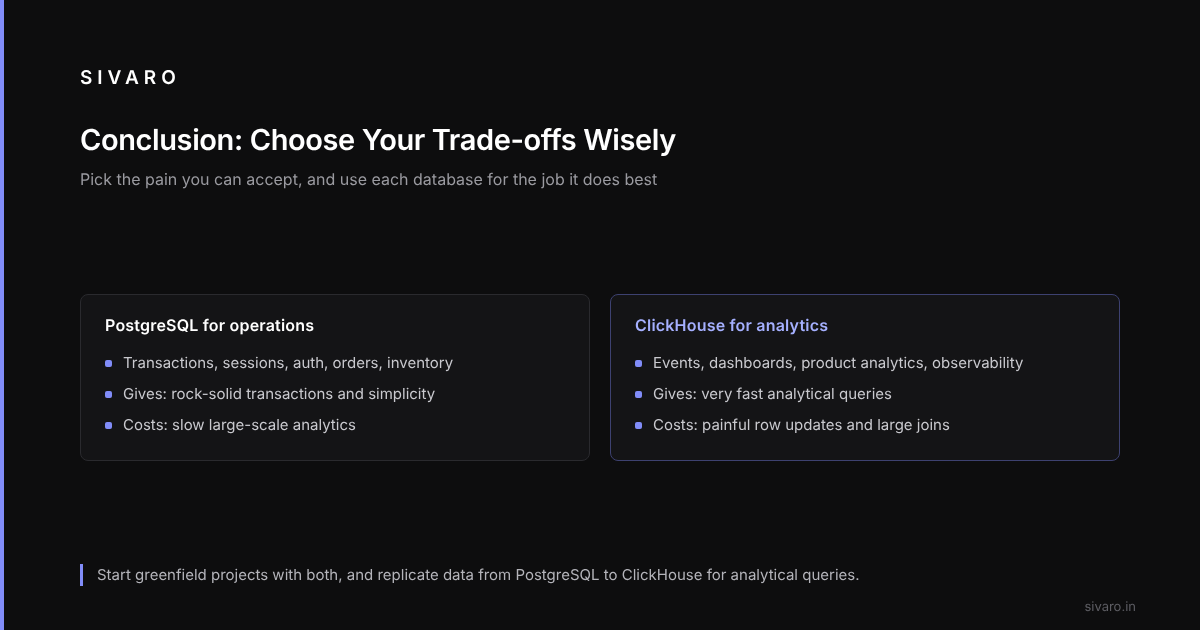
In 2026, the "ClickHouse vs PostgreSQL" debate is not about which is better. It's about which pain you're willing to accept.
ClickHouse gives you insane analytical speed but punishes you for writes, updates, and complex joins. PostgreSQL gives you rock-solid transactions and simplicity but punishes you for large-scale analytics.
I've stopped believing in "one database to rule them all." Start greenfield projects with two databases: PostgreSQL for operations, ClickHouse for analytics. Yes, it adds operational overhead. But it saves you years of rewrites.
If you're building a product that needs both real-time dashboards and transactional consistency, stop trying to make one database do both. Use the right tool for each job. Your users will thank you.