This debate is everywhere.
Kafka and NiFi get lumped together as "data streaming tools." That's sloppy. They solve different problems, and if you pick the wrong one, you'll waste months rewriting pipelines.
You'll learn exactly when to use Kafka, when to use NiFi, and when you need both. No fluff. No "both have merits." Real trade-offs, real numbers.
What Kafka Actually Does Well
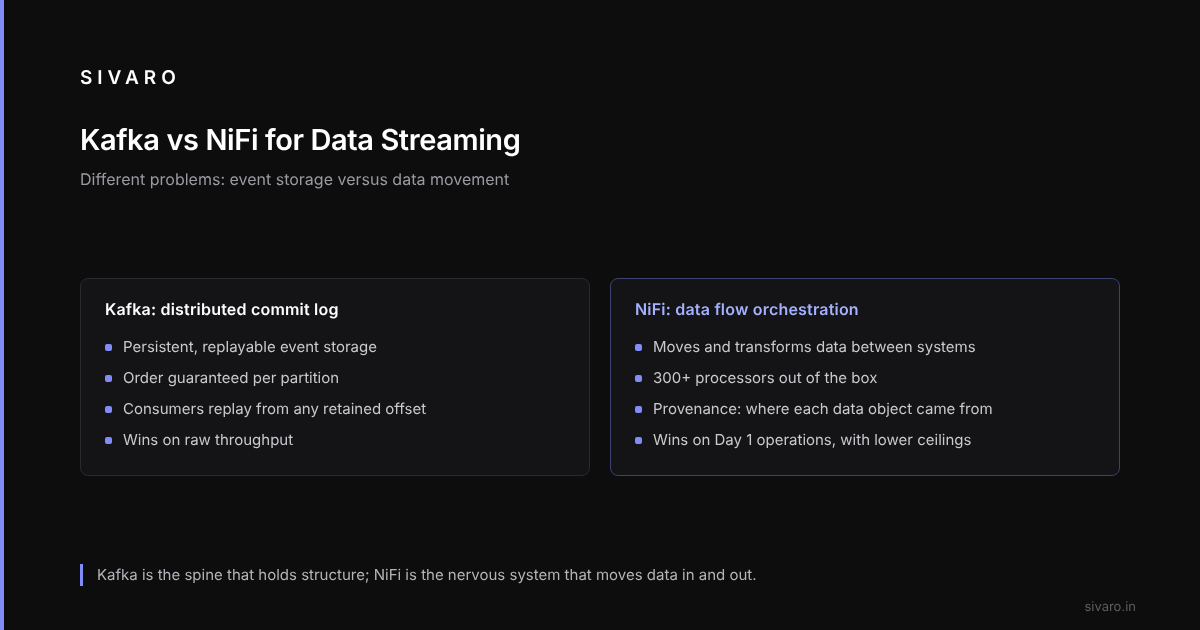
Kafka is a distributed commit log. That's it. It's not a data flow engine. It's not a metadata scrapbook. It's a high-throughput, durable, replayable event store.
The core strength is simple: write once, read many times. With proper kafka multi broker cluster setup, you get horizontal scalability, fault tolerance, and low latency at high throughput.
Most people think Kafka is "slow" because of disk I/O. That's wrong. Kafka writes to the filesystem sequentially—page cache, not random I/O. Modern SSDs make this screaming fast. Kafka vs Pulsar: Performance, Features, and Architecture shows Kafka's log compaction and retention policies give you fine-grained control over durability vs. performance.
Where Kafka dominates:
- Event sourcing / CQRS patterns
- Metrics / telemetry ingestion
- Log aggregation (the original use case)
- Replaying messages for state reconstruction
- Decoupling microservices at scale
But here's the rub: Kafka does not move data. It stores it. If you need to pull data from a legacy SQL Server, transform XML to JSON, and drop it into S3—Kafka won't help you there. That's a different tool's job.
Where NiFi Shines (And Kafka Doesn't)
NiFi is a data flow orchestration tool. Think of it as a visual programming environment for data pipelines. You drag processors onto a canvas, connect them, and data moves.
NiFi is not just a UI for Kafka.
NiFi's superpower is provenance. Every dataflow step records where a data object came from, what processor transformed it, and where it went. Need to audit exactly which files got ingested from an FTP server and why one failed? NiFi gives you an interactive graph of that flow within minutes. Try doing that with Kafka consumer logs.
Another NiFi strength: connector breadth. The tool ships with 300+ processors out of the box. FTP, SFTP, HTTP, JMS, AWS S3, Google Cloud Storage, HDFS, Splunk, and yes, Kafka producers and consumers. You can build a flow that polls an uncooperative legacy database via JDBC, normalizes the records, and pushes them to a Kafka topic—all without writing a single line of Java.
A typical fit: ingesting HL7 messages from multiple hospital systems, where each message needs validation, de-duplication, and routing to different downstream APIs. NiFi's backpressure and prioritization (flow file prioritizers) prevent overload storms in that kind of flow.
But—and this is important—NiFi is not a streaming platform. It's a streaming processor of sorts, but it doesn't offer Kafka's durability guarantees. If your NiFi cluster goes down mid-flow, you can lose data unless you've enabled the Write-ahead Log (WAL) or used persistent provenance. And throughput? NiFi tops out around 500K to 1M events per second on a decent cluster, depending on processor complexity. Kafka can do 10x that.
The Real Difference: Stream Processing vs Data Flow Orchestration
Most people think the debate "kafka vs nifi for data streaming" is about which tool is faster. It's not. It's about what problem you're solving.
Kafka solves: persistent, replayable event storage.
NiFi solves: data movement with provenance and transformation.
If you need a message bus that guarantees order per partition and lets consumers replay from any point, pick Kafka. If you need to move files from one system to another, transform data formats, and track every step for compliance, pick NiFi.
The confusion happens because both can do parts of each other's job. NiFi can write to Kafka. Kafka can feed a stream processor (like Flink) that does transformations. But using Kafka as a data flow orchestrator is painful. You'd need to build consumers that poll, transform, and push to targets. That's work. Using NiFi as an event log is also painful. You lose independent consumers and replayability.
Using NiFi as a message queue for microservices fails in a predictable way. A single NiFi processor routes events between services. It works at low volume. Then one service responds slowly. NiFi's backpressure kicks in. The entire flow stalls. All services block. That's not a message queue design. Kafka handles this scenario natively through consumer group rebalancing and offset management.
When You Need Both: The Kafka-NiFi Hybrid
For complex data pipelines, Kafka plus NiFi working together is often the best architecture.
Kafka sits as the central durable buffer. NiFi acts as the data ingestion and egress layer.
A typical design:
- NiFi flows poll multiple legacy systems (IBM MQ, flat files on SFTP, database CDC via Debezium).
- NiFi transforms data into Avro schemas and publishes to Kafka topics.
- Kafka stores the events durably (7 days retention, with an S3 sink for historical archive).
- Multiple consumers: real-time fraud detection (Flink), batch analytics (Spark), and a web UI.
- NiFi also subscribes to a separate "commanded" topic to route responses back to legacy systems.
This design gives full auditability. When auditors ask "where did this transaction come from?", NiFi's provenance traces it back to the exact SFTP file, timestamp, and transformation step.
The key insight: Kafka is the spine. NiFi is the nervous system. The spine holds structure; the nervous system moves data in and out.
Performance Reality Check
Let's talk numbers.
Kafka (properly configured):
- Latency: 2-10ms at p99 under moderate load (10K msg/s per partition).
- Throughput: Easily 500K-1M msg/s per broker with replication factor 3. Larger clusters scale linearly.
- Durability: ack=all with min.insync.replicas=2 guarantees no loss even if one broker dies.
NiFi (with WAL enabled and decent hardware):
- Latency: 50-200ms per flow hop. Complex transformations (like JSON-to-Avro with schema validation) add more.
- Throughput: 100K-500K flow files per second depending on processor complexity. Beyond that, you need to scale horizontally by adding nodes to the NiFi cluster.
- Durability: Without WAL, data loss possible on crash. With WAL and persistent provenance, approximately at-least-once.
Both can do exactly-once if you configure them right (Kafka transactions, NiFi with distributed map cache and idempotent processors). It's not trivial.
Kafka wins on raw throughput. But throughput isn't everything. If your pipeline needs to route based on content, decompress archives, and call external APIs, NiFi's built-in processors outperform hand-rolled Kafka consumers by a wide margin in developer productivity.
Kafka Multi-Broker Cluster Setup
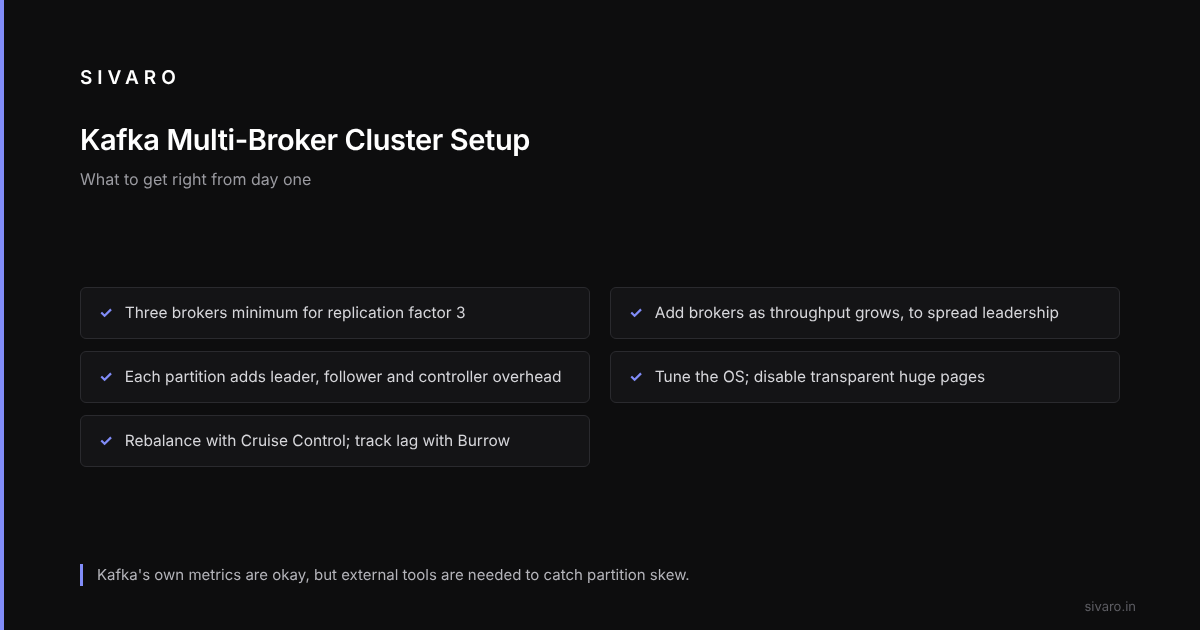
You can't talk about kafka vs nifi for data streaming without addressing the operational overhead of kafka multi broker cluster setup. Here's what to know from day one.
First, broker count matters more than you think. Three brokers is the minimum for a resilient cluster with replication factor 3. But if you're handling 500K+ msg/s, you need at least five brokers to distribute leadership.
Second, partition count is a trap. More partitions give more parallelism. But each partition adds overhead for leaders, followers, and controller state. For Kafka 3.8 (latest as of July 2026), the recommended max is 4,000 partitions per broker, 200,000 per cluster. Above that, zookeeper (or KRaft) metadata operations slow down.
Third, OS tuning is mandatory. Dirty ratio, vm.swappiness, page cache. For example, set vm.dirty_ratio=60, vm.dirty_background_ratio=2. Also, disable transparent huge pages. Save yourself the heartache.
Fourth, monitoring is non-negotiable. Use Cruise Control for rebalancing. Use Burrow for consumer lag. Kafka's own metrics are okay, but you need external tools to catch partition skew.
If this sounds complex, it is. NiFi setup is simpler: download, configure a few properties, start cluster. But that simplicity comes with lower ceilings.
Operational Complexity Comparison
Let's get honest.
Running Kafka in production is hard. It's a distributed system with many moving parts. Broker crashes, partition reassignments, consumer rebalancing, disk space management—all require experienced operators. Even teams with two DevOps engineers can struggle to keep a 10-broker cluster healthy.
NiFi is easier to operate day-to-day. You install the binary, configure a shared state provider (ZooKeeper or embedded server), and you're running. Its UI gives you real-time flow metrics. No CLI hunting. No grep through server logs to find a missing configuration.
But NiFi hides complexity that bites you later. Flow files pile up in queues if a downstream processor fails. You need to set backpressure limits (e.g., max 10K flow files). Without them, the NiFi process runs out of memory.
For disaster recovery, Kafka is better. You can spin up a new cluster and point consumers to the same Kafka topics if you use external offsets and replication. NiFi's state is more fragile. Its flow definitions and provenance can be backed up, but ongoing flows lose their place.
Bottom line: NiFi wins on Day 1 operations. Kafka wins on sustained production reliability at scale.
Cost Considerations
Pricing is where people make emotional decisions.
Kafka: Open source, but you need hardware. Three broker VMs at $300/month each (AWS r6i.large) = $900/month base. Add ZooKeeper nodes (or KRaft) and monitoring infrastructure. Total: $1,500-$3,000/month for a modest cluster. Managed services like Confluent Cloud cost more but reduce operational overhead. For a medium throughput pipeline (50K msg/s), Confluent Cloud runs about $500/month.
NiFi: Also open source. A three-node NiFi cluster on t3.large (same ballpark as Kafka brokers) runs about $500/month. Managed NiFi? Not many options. Cloudera DataFlow offers a managed NiFi service (formerly Hortonworks), but it's enterprise-priced—expect $10,000+/year per node.
The hidden cost: developer time.
- Writing custom processors in NiFi? That's Java coding. Each custom processor takes a day to build and test.
- Writing Kafka consumers for multiple targets? That's also development time.
NiFi tends to be cheaper for projects with lots of varied data sources and transformations, even though hardware costs are similar. The drag-and-drop UI lets non-specialist engineers build flows. Kafka is cheaper for high-throughput homogenous pipelines where you need maximum performance.
Decision Framework: How to Choose
It comes down to five questions.
1. Do you need replayable event history?
- Yes: Kafka.
- No: NiFi.
2. Is your data coming from multiple heterogeneous sources?
- Yes: NiFi (its connectors reduce integration time by 10x).
- No: Kafka.
3. Do you need compliance audit trails per record?
- Yes: NiFi (provenance is unparalleled).
- No: Kafka (you'd need to build your own audit infrastructure).
4. What's your target throughput?
- < 200K events/second: Either works. Choose based on other factors.
- 200K-1M events/second: NiFi starts struggling. Go Kafka.
-
1M events/second: Kafka is your only option.
5. Do you have ops bandwidth to manage a distributed commit log?
- Low: Pick NiFi (but be ready for scaling limitations).
- High: Kafka delivers more power.
If you answered "both" to multiple questions, use the hybrid approach described earlier.
FAQ: Kafka vs NiFi for Data Streaming
Q: Is NiFi a replacement for Kafka?
No. They solve different problems. NiFi moves data. Kafka stores data. They complement each other.
Q: Can I use Kafka without NiFi?
Absolutely. Many production systems run Kafka alone, especially for pub/sub microservices. But you'll need to write custom connectors for each data source.
Q: Is NiFi good for real-time streaming?
NiFi is real-time in the sense that it processes data as it arrives. But its latency is higher than Kafka, and its throughput ceiling is lower. For sub-100ms streaming, Kafka + Flink is better.
Q: How do I set up Kafka with NiFi?
Simple: NiFi's PublishKafka processor writes to Kafka topics. ConsumeKafka reads from topics into NiFi flows. Use Avro serialization with Schema Registry for schema evolution.
Q: Does NiFi support exactly-once processing?
Yes, but it requires careful configuration: idempotent processors, distributed map cache for dedup, and using the Write-ahead Log. Kafka has built-in transactions for exactly-once.
Q: Which one is easier to scale?
Kafka scales horizontally by adding brokers and increasing partitions. NiFi scales by adding nodes to the cluster, but flow file queue management becomes complex above 500K flow files.
Q: What's the best cloud service for these?
For Kafka: AWS MSK, Confluent Cloud, or self-managed. For NiFi: Cloudera DataFlow or self-managed on EC2/Kubernetes.
Q: I have a legacy system that only outputs flat files. Should I use NiFi or Kafka?
NiFi. Its processors for FTP, SFTP, and file monitoring are built-in. Using Kafka would require writing a file ingestion agent.
Final Thoughts
Kafka and NiFi are not enemies. They're partners.
If you're evaluating "kafka vs nifi for data streaming" right now, stop comparing speed benchmarks. Compare job descriptions:
- Kafka is an event store.
- NiFi is a data flow conductor.
Use the right tool for the job. Build the hybrid when you need both.
And whatever you choose, test it with real data volumes before going to production. Not with 1,000 events. With one million.
Trust me on that.