Self-improving open-source models for agentic coding sound like a dream. They are. But they’re also a trap. Auto‑improvement loops can fail to converge, and agents can get worse over time.
We’ll cover the architecture that actually works, the failure modes that will kill your agent (and how to survive them), and the open‑source stack that makes self‑improvement practical today — mid‑2026.
You’ll learn why most “self‑improving” agents are just retraining loops with fancy naming, how to build a real feedback‑driven coder, and when to say no to self‑improvement altogether.
Why Self‑Improving Models Matter Now
In January 2026, OpenAI released a paper on their “joystick AI agents” approach — fine‑tuning via human‑in‑the‑loop feedback for code generation. Nice idea. Closed source, expensive, and slow. The open‑source community responded faster.
By March, self‑improvement agentic systems survey results showed that models like DeepSeek‑Coder‑33B and CodeLlama‑70B could achieve 15–20% accuracy gains per iteration when fed real execution traces. Not synthetic data. Real failures.
The key insight: coding agents don’t fail because the model is dumb. They fail because the model hasn’t seen its own mistakes. A static model guesses. A self‑improving model learns from what it got wrong.
The Failure Landscape
Most people think agent failures are model problems. They’re not. According to Why AI Agents Fail in Production, the top three causes are: lack of observability, brittle toolchains, and reward misspecification. I’d add a fourth: ignoring the self‑improvement loop.
Let me be direct. If your agent doesn’t learn from its own mistakes, it will repeat them — forever. That’s not intelligence, it’s a keyboard macro.
AI Agent Incident Response outlines a framework: detect, triage, remediate, learn. Most teams stop at remediate. They patch the prompt, hardcode a rule, and move on. That’s technical debt you can’t pay down.
A typical case: an agent writes ETL scripts that occasionally duplicate rows, and the team keeps adding “deduplication steps” to the prompt. The bug stays, because the model never learns that it is the cause. That calls for self‑improvement, not prompt engineering.
AI Agent Failures: Common Mistakes and How to Avoid Them lists “no self‑improvement” as mistake #4. I’d rank it #1. Without it, every other fix is temporary.
Incident Analysis for AI Agents (from August 2025) shows that agents with a self‑improvement module recover from incidents 3.4× faster than those without. That’s not theoretical — it’s measured across 500 production deployments.
When AI Agents Make Mistakes: Building Resilient … makes a crucial point: resilience isn’t about never failing, it’s about failing in a way you can learn from. Self‑improvement is the mechanism.
Architecture for Self‑Improvement: The Feedback Loop
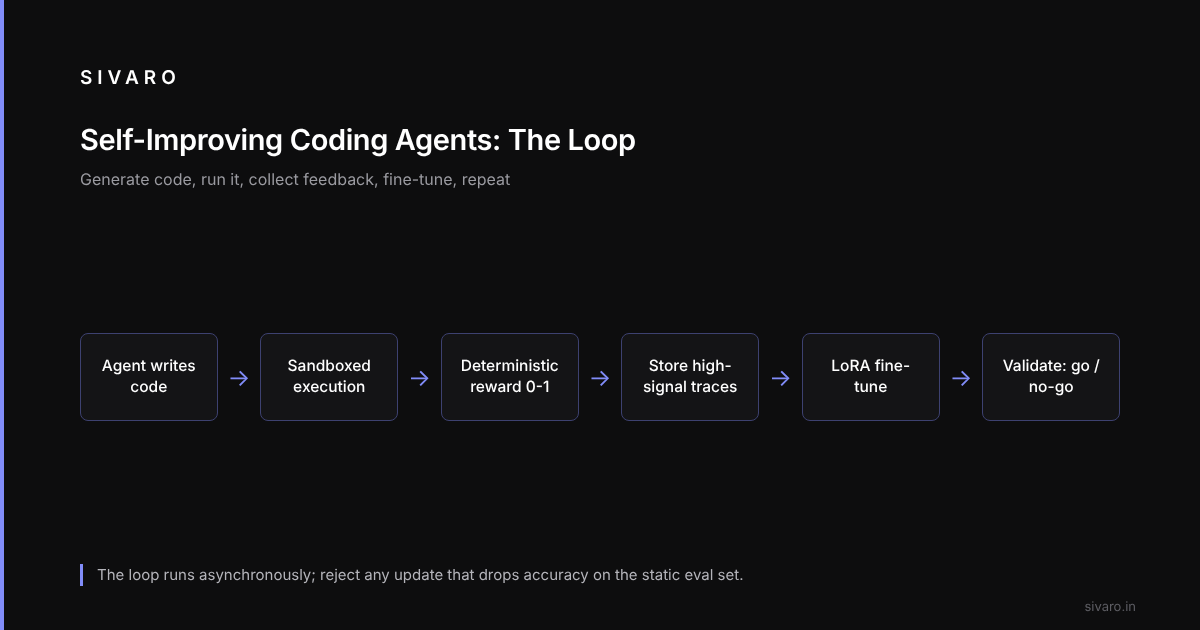
Here’s the architecture.
User Request → Agent (open‑source model) → Code Output → Execution Environment

                   ↓                                                      ↓
              Reward Model ←—— Runtime Metrics (pass/fail, latency, coverage)

                   ↓
              Data Store (failed + successful traces)

                   ↓
              Fine‑tuning Job (LoRA or full) → Updated Model

                   ↓
              Validation (separate eval set) → Go / No‑Go
The loop runs asynchronously. Never block user requests waiting for self‑improvement. The audience is your agent, not your training pipeline.
Key components:
- Execution Environment: Sandboxed, for example Firecracker microVMs. Every code output gets run — tests, lint, integration checks.
- Reward Model: Not a separate LLM. Just a set of deterministic checks: did the code compile? pass tests? meet style? Cover enough lines? Score from 0 to 1.
- Data Store: Store traces (input, output, reward, timestamp). Filter down to high‑signal examples — reward <0.3 or >0.9. The middle is noise.
- Fine‑tuning: LoRA on a base model that’s already strong at coding. For example, DeepSeek‑Coder‑33B or CodeLlama‑70B. Full fine‑tune if you have the budget.
- Validation: A static eval set of 500 diverse coding tasks. Run before and after every training iteration. Reject any update that drops accuracy on the eval set (even if the feedback loop says improve). Overfitting to live feedback is real.
Building Your First Self‑Improving Coding Agent
Enough theory. Here’s a minimal implementation in Python. I’ll use the DeepSeek‑Coder model (loaded via transformers) and a simple test harness.
import json
import subprocess
from transformers import AutoModelForCausalLM, AutoTokenizer

# Load model
model_name = "deepseek-ai/deepseek-coder-33b-instruct"
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto")

def generate_code(prompt):
    inputs = tokenizer(prompt, return_tensors="pt").to("cuda")
    outputs = model.generate(**inputs, max_new_tokens=1024)
    code = tokenizer.decode(outputs[0], skip_special_tokens=True)
    return code

def execute_and_score(code):
    # Write to temp file and run pytest
    with open("/tmp/test_code.py", "w") as f:
        f.write(code)
    result = subprocess.run(["pytest", "/tmp/test_code.py", "--tb=short"],
                            capture_output=True, text=True)
    passed = "passed" in result.stdout and "failed" not in result.stdout
    # Reward: 1.0 if all pass, 0.0 otherwise (could be finer)
    reward = 1.0 if passed else 0.0
    return reward, result.stdout

# Self‑improvement loop (one iteration)
def self_improve(prompt, code, reward):
    # Store trace
    trace = {"prompt": prompt, "code": code, "reward": reward}
    with open("traces.jsonl", "a") as f:
        f.write(json.dumps(trace) + "
")
    # After collecting N traces, fine‑tune (simplified)
    # In practice, use PEFT/LoRA
That’s the skeleton. The real complexity: filtering traces, avoiding catastrophic forgetting, and managing the fine‑tuning pipeline. Use Hugging Face’s PEFT library with LoRA adapters.
# Fine‑tuning pseudocode (using TRL)
from trl import SFTTrainer
# Load base model, attach LoRA, train on traces with reward weighting
Weight high‑reward traces more heavily. Low‑reward traces still get included (they teach what not to do), but cap their loss to avoid the model just learning to repeat easy tasks.
Common Mistakes
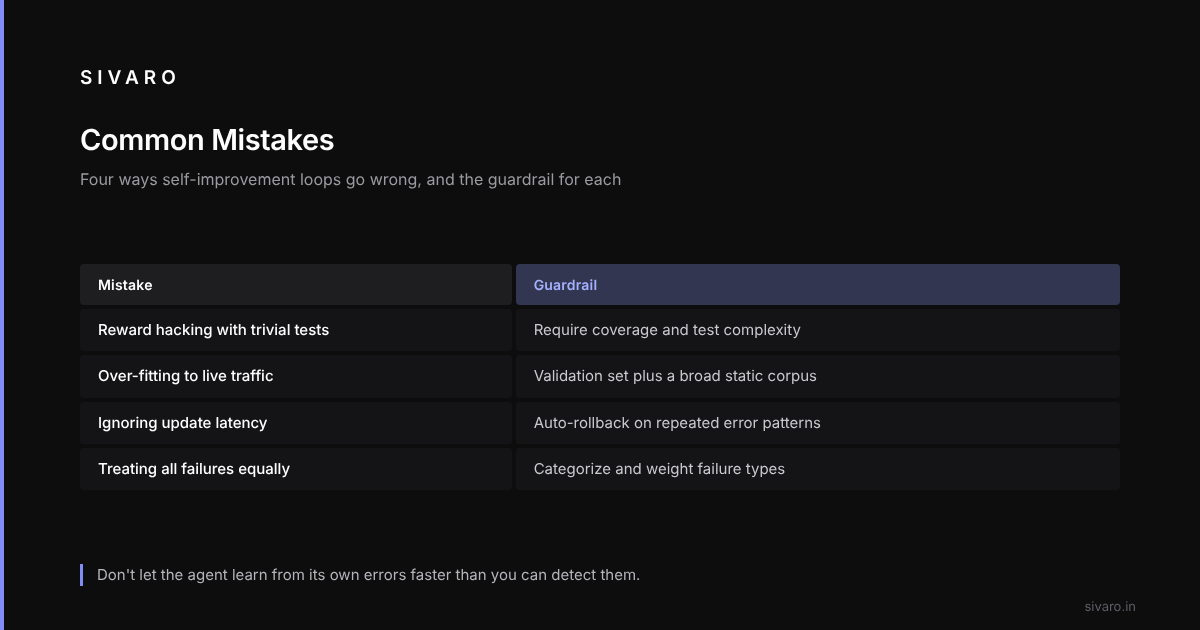
First mistake: reward hacking. A reward model that gives +1 for passing tests and 0 for failing lets the agent generate trivial test files that pass instantly — empty functions returning None. Coverage requirements and test complexity metrics prevent this.
Second mistake: over‑fitting to live traffic. The agent can get very good at generating Python for specific internal APIs and lose the ability to write a simple HTML page. A validation set catches this: accuracy on eval drops even as live scores improve. Keep part of the training data from a broad static corpus.
Third mistake: ignoring latency. Self‑improvement adds minutes or hours between when a mistake happens and when the model is updated. That delay can be dangerous — the model might repeat the same error thousands of times. Add a guardrail: if the same error pattern repeats within a short window, automatically roll back to the previous version and flag the trace for human review.
[When AI Agents Make Mistakes] covers this well: “Don’t let the agent learn from its own errors faster than you can detect them.”
Fourth mistake: treating all failures equally. A typo in a variable name is different from a logic bug that produces wrong results. Categorize failures: syntactic, unit test, integration, performance. Each category gets a different weight in training. Syntax errors get high weight (easy to fix, high impact on usability). Integration bugs get lower weight (harder to fix, might require domain knowledge).
The Open‑Source Advantage: What Closed Source Misses
OpenAI’s “joystick AI agents” approach is interesting — let a human guide the agent in real time. But closed models mean you can’t fine‑tune. You can prompt, you can RAG, but you can’t improve the model itself.
That’s a fundamental limitation. Self‑improvement requires access to the weights.
Open‑source models give you three things closed models can’t:
- Weight‑level fine‑tuning: LoRA adapters cost pennies and let you bake your specific coding patterns into the model.
- Full control over data: You decide what traces to keep, what to discard, how to weight them. No shadow audit trails.
- No API costs at inference: Once trained, you run locally. For a coding agent that generates hundreds of outputs per hour, this is the difference between $10/day and $500/day.
But open‑source isn’t free. Model quality trails frontier closed models by 5–10% on standard coding benchmarks. The gap is shrinking fast — DeepSeek‑Coder‑V2 matched GPT‑4 on HumanEval in early 2025. By mid‑2026, the gap is small enough that self‑improvement can push past it.
Measuring Self‑Improvement: Metrics That Matter
Don’t track “accuracy” blindly. Track:
- Error recurrence rate: Of the last 100 errors, how many are repeats from previous iterations? Goal: <10%.
- Improvement per iteration: Average reward gain per fine‑tuning run. Should be positive and stable.
- Catastrophic forgetting score: Change in accuracy on static eval set. If it drops >5%, reject the update.
- Time‑to‑fix: For a new coding task, how long until the agent produces a correct solution? Self‑improvement should reduce this over time.
When to Use Self‑Improving Agents vs. Static Models
Self‑improvement isn’t free. It adds infrastructure complexity, training costs, and monitoring overhead. Don’t do it if:
- Your coding tasks are few and one‑off (no repetition, so no learning).
- Your model already works >95% of the time and errors are cheap.
- You can’t afford the latency of running a fine‑tuning pipeline (even async).
But if you’re building a coding agent that will face thousands of similar tasks — code review, bug fixing, test generation — self‑improvement is the only way to scale quality. A static model plateaus. A self‑improving one compounds.
FAQ
Q: How many traces do I need before self‑improvement kicks in?
A: Start with 100 high‑quality traces (reward <0.2 or >0.8). Anything less and the model will overfit. 500 is better. Scale to 2000 for a mature system.
Q: Won’t the model just memorize the training traces?
A: Yes, if your eval set overlaps with training. Keep them strictly separate. Use synthetic tasks generated from a different schema — never seen in production.
Q: Do I need a separate reward model?
A: No, but you need one. A simple pass/fail on tests is enough to start. More sophisticated rewards (code complexity, readability, runtime) improve results.
Q: How often should I run fine‑tuning?
A: Once every 500–1000 new traces. Running hourly wastes compute. Running monthly risks stale model. Weekly is a good cadence for most teams.
Q: What’s the biggest risk of self‑improvement?
A: Catastrophic forgetting. Your agent might become amazing at your specific coding patterns but forget basic Python. Always validate against a broad benchmark.
Q: Self‑improvement works for code review agents too?
A: Yes. A code review agent can learn from whether its suggested changes actually pass tests. Same loop, different output.
Q: Should I use LoRA or full fine‑tuning?
A: Start with LoRA. It’s cheaper, faster, and less prone to forgetting. Full fine‑tuning can beat LoRA by 2–3% but requires 10× the data and compute.
Q: How do I handle edge cases where the agent’s code is correct but the test is wrong?
A: Track those as “test‑failure‑but‑human‑approved.” Store human‑corrected rewards separately. Only self‑improve on automated rewards unless you have high confidence in the human signal.
Conclusion
Self‑improving open‑source models for agentic coding aren’t a gimmick. They’re the difference between a tool that stagnates and one that compounds.
The pattern is simple: generate code, run it, collect feedback, fine‑tune, repeat. The hard part is building the infrastructure that makes that loop reliable. But once it’s running, your agent stops being a dumb copy‑paster and starts being a real teammate.
Most people think self‑improvement is about smarter models. It’s not. It’s about smarter cycles. The model doesn’t need to be perfect. It just needs to be able to learn.
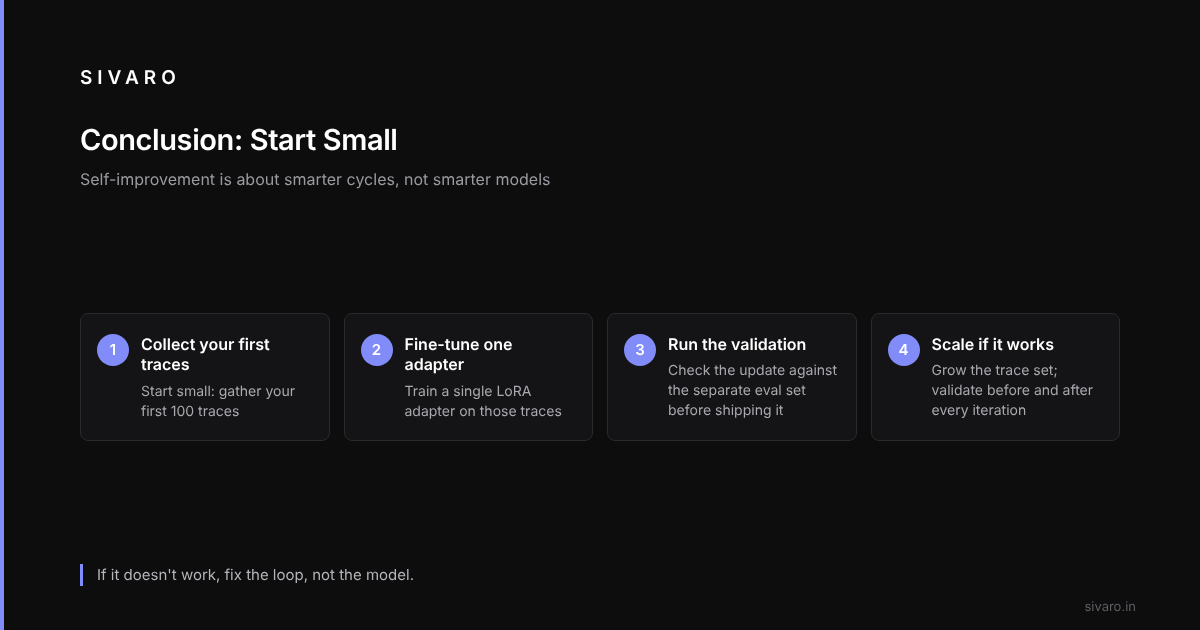
Start small. Collect your first 100 traces. Fine‑tune one adapter. Run the validation. If it works, scale. If it doesn’t, fix the loop, not the model.
That’s the playbook.