Eight H100s sound like plenty for a team of agents. They often aren't.
Agents reason through multi-step tool calls, retrieve data from a vector store, and keep a conversation history that can span 50 turns. If each agent request eats minutes of GPU compute, a few concurrent agents saturate the cluster on the first request and queue everything else. Users then wait minutes for a reply.
That's the problem with "what size gpu cluster do i need for ai agents" — it's not just about model size. It's about concurrency, latency, and the hidden cost of agent loops.
We're in July 2026. AI agents are the dominant use case for production LLMs. Teams scaling from prototypes to 1,000+ concurrent users ask the same question. The answer is never a single number.
The Basics of Distributed Training for Agent Models
You can't size a cluster without understanding what are the basics of distributed training? — because most agent models today are fine-tuned from base LLMs. Even if you're using a frontier API, you'll eventually want a custom small model for tool-calling or routing.
Distributed training splits the data and model across multiple GPUs. Two main approaches:
- Data parallelism: each GPU holds a full copy of the model, processes a different batch, syncs gradients. Works for models up to ~7B on a single node.
- Model parallelism: split the model layers across GPUs. Required for 70B+ models.
There's also pipeline parallelism (chunk layers into stages) and tensor parallelism (split individual matrix ops). The latter is what makes training a Llama 3 70B on 8 H100s possible — barely.
A GPU cluster is just a bunch of nodes connected by high-speed networking (InfiniBand or NVLink). Each node has 8 GPUs. A single H100 node gives you 640GB of HBM3 memory (80GB per GPU). Enough for a 70B model with decent batch size.
But agent training introduces a twist: you're not just doing next-token prediction. You're training reward models, RLHF, or behavioral cloning from agent trajectories. That means longer sequences and more memory per sample. A single agent rollout can be 8K tokens. Your batch size drops. Your utilization tanks.
Teams often assume a 7B model fits on one H100 for training. It does — with batch size 2. That's garbage throughput. You need at least 4 GPUs to get reasonable utilization.
So what are the basics of distributed training? It's about balancing compute, memory, and communication overhead. If you're training a 7B agent model, plan for at least 4 GPUs. For 70B, you need 8–32 GPUs depending on the parallelism strategy and sequence length.
Calculating Your GPU Needs: A Practical Framework
The question [what size gpu cluster do i need for ai agents] breaks down into three dimensions:
- Training – one‑time or periodic fine‑tuning
- Inference – serving agents to users
- Agent overhead – tool calls, memory retrieval, code execution
Most people only think about the first two. The third kills you.
Here's the framework I use:
Step 1: Define your agent workload
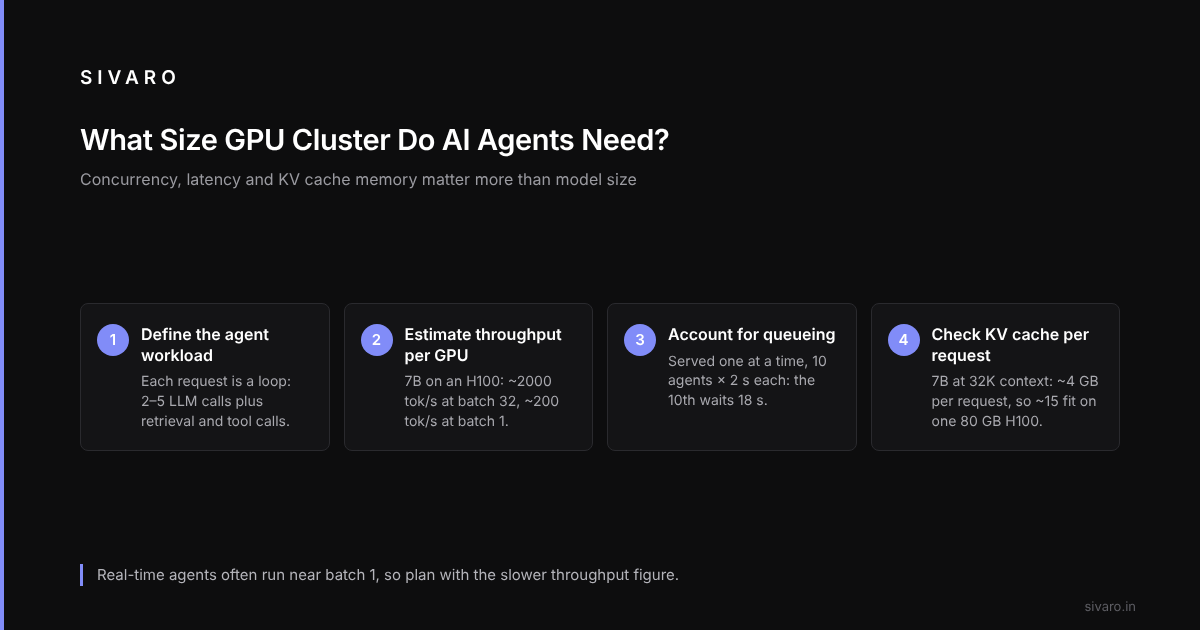
An agent call isn't a single inference. It's a loop. Each turn of the loop may require:
- One LLM inference (generate next action)
- One retrieval (embedding + vector search)
- Possibly a code execution or API call
- Another LLM inference to parse results
That's 2–5 LLM calls per user request. And the context window grows with each turn — often hitting 32K tokens.
Step 2: Estimate inference throughput per GPU
For a 7B model on an H100:
- With batching of 32: ~2000 tokens/second per GPU (FP16)
- For a 400‑token output, that's ~0.2 seconds per inference
- But if you're doing batch size 1 (common for real‑time agents), throughput drops to ~200 tokens/second → 2 seconds per inference
For a 70B model on an H100:
- Batch size 1: ~50 tokens/second → 8 seconds per 400‑token output
- Batch size 32 can get ~700 tokens/second, but then latency becomes uneven
Agent workloads are latency‑sensitive. If a user hears "I'm thinking..." for 10 seconds, they churn. So you often can't batch aggressively.
Step 3: Multiply by concurrency
If you expect 100 simultaneous agent sessions, each session makes ~3 LLM calls *average 2 seconds per call = 6 seconds of GPU time. You need to process 600 GPU‑seconds per second. That's 600 concurrent GPU‑seconds / (each GPU provides 1 second per second) → 600 GPUs.
That number is high. But it's real.
How many gpus do you need for llm training? That's simpler: use the 5 Key Considerations when Building an AI & GPU Cluster – model size, dataset size, acceptable training time, budget, and cooling. A 70B model trained on 1T tokens can take 30 days on 8 GPUs. Cut to 5 days with 64 GPUs. Training is a batch problem, inference is a streaming nightmare.
Training vs. Inference: The Hidden Factor
It is tempting to treat this as a numbers game — just compute FLOPs and see what fits. In practice it's about memory bandwidth.
Training is memory bound in a different way than inference.
- Training: you have huge activations that need to be stored for backward pass. This forces smaller batch sizes. More GPUs = more total memory = faster training.
- Inference: you have KV cache growing with sequence length. An agent with 32K context uses ~4GB of KV cache per request. On an 80GB H100, you can fit maybe 15 concurrent requests before running out of memory — even though compute utilization is low.
So inference is often memory‑capacity gated, not compute gated.
For a cluster serving agents, you need to consider:
- KV cache offloading – moving old context to CPU. Adds latency but allows more concurrency.
- Flash Attention – reduces memory but doesn't eliminate it.
- speculative decoding – uses a small draft model to generate multiple tokens per GPU call, effectively increasing throughput.
A 7B agent model with speculative decoding (for example a 160M draft model) can get several times the throughput on the same H100 node. That can shrink the cluster you need by a similar factor.
But it's not free. You need extra VRAM for the draft model. And the acceptance rate drops for complex tasks.
Multi-Agent Concurrency and Latency Budgets
Scheduling is the factor teams most often miss.
If you run 10 agents on a single GPU, they queue up. Each agent might have 2 seconds of compute, but the queue means the 10th agent waits 18 seconds. Users experience that as "the agent is broken."
You need enough GPUs to flatten that queue. The formula:
GPUs needed = (agent_concurrency * avg_latency_per_agent) / target_latency_seconds
Example:
- Concurrency = 100 agents
- Avg agent latency (total, including tool calls) = 5 seconds
- Target end‑to‑end latency = 2 seconds
- GPUs = (100 * 5) / 2 = 250
That's a cluster of 32 nodes (8 GPUs each). With H100s at ~$30K each, that's $7.5M capital. Ouch.
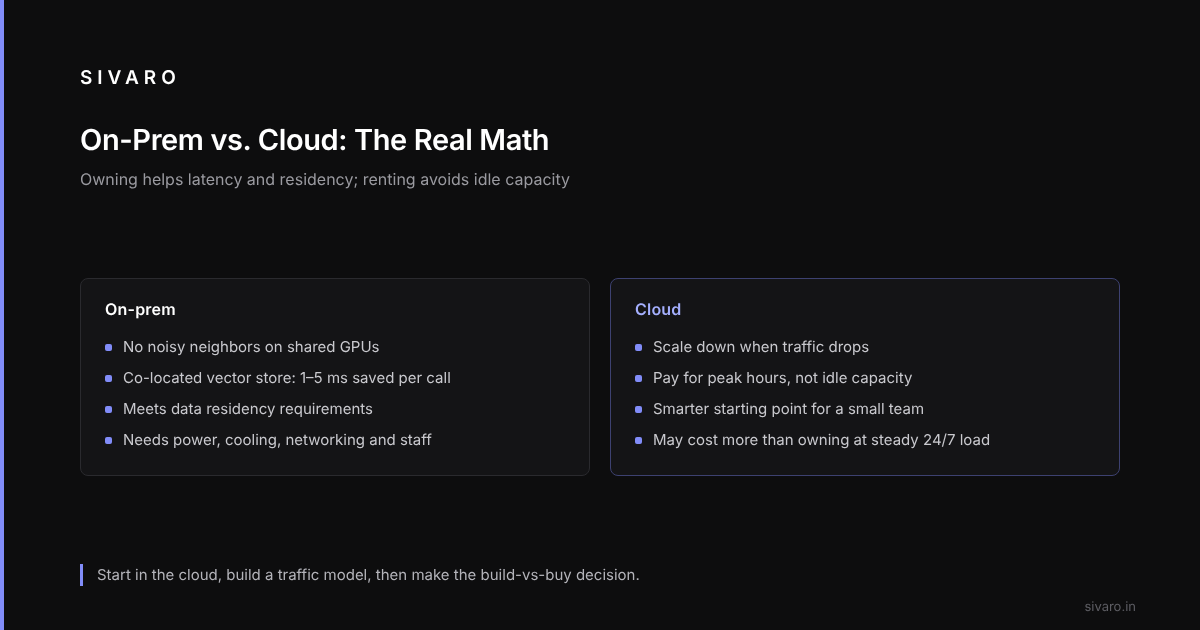
But wait — most agents don't need all GPUs at once. The concurrency might be 100 at peak, 10 at low traffic. You can scale down in the cloud.
Vast.ai: Rent GPUs gives you spot pricing. A H100 costs about $1.50/hour there. For 250 GPUs, that's $375/hour. If peak lasts 4 hours a day, that's $1,500/day — $45K/month. Far less than owning.
But if you're running 24/7 with constant load, owning might be cheaper after 12 months. The break‑even point depends on your utilization.
On-Prem vs. Cloud: The Real Math
I'm biased toward on‑prem for production inference. Why?
- No noisy neighbor. When you share GPUs in the cloud, you can get jitter. A 2‑second inference becomes 4 seconds because the neighboring VM is doing a large matrix multiply. For agents, jitter destroys user experience.
- Latency. If your agents call your vector store that's also on‑prem, you save 1–5ms per roundtrip. Over 10 tool calls, that's 50ms. Doesn't sound like much, but it compounds.
- Data residency. Many teams in finance and healthcare can't send user queries to cloud GPUs.
But What is the best option to setup on premise GPU cluster for a small company? — the answer depends on your power budget. A single node of 8 H100s pulls 7kW. You need 30A 208V circuits. And cooling. And redundant networking. And a staff to manage it.
For a team of 10, it's often smarter to start with cloud, build your traffic model, then make the build‑vs‑buy decision.
Size for Inference, Rent Training
A common and expensive mistake is to buy a large cluster to "own the stack" — dozens of H100 nodes, InfiniBand, Slurm, an ops team — and then find that inference needs only a fraction of it while the rest sits idle between quarterly training runs.
The rule: size for peak inference, rent training. Training is bursty. Inference is constant. Buy the inference cluster, rent training on Vast.ai or similar.
Code Example: Sizing Estimator in Python
Here's a function to estimate the minimum number of GPUs for agent inference. It's rough, but it beats guessing.
def estimate_agent_gpus(
    model_size_billion: int,
    avg_agent_turns: int,
    tokens_per_output: int,
    concurrency: int,
    target_latency_seconds: float,
    gpu_memory_gb: int = 80,
    gpu_tokens_per_second_batch1: int = 200,  # for 7B, adjust for larger models
):
    """
    Estimate minimum GPU count for AI agent inference.
    """
    # Estimate VRAM per request (KV cache + model overhead)
    kv_cache_gb = (model_size_billion / 7) * 0.1 * avg_agent_turns * tokens_per_output / 1000
    model_fit = model_size_billion / 7  # 7B ~ 14GB fp16, scaling
    vram_per_request = model_fit + kv_cache_gb

    max_concurrent_per_gpu = int(gpu_memory_gb / vram_per_request)
    if max_concurrent_per_gpu < 1:
        max_concurrent_per_gpu = 1

    # Average latency per agent (in seconds)
    latency_per_agent = avg_agent_turns * (tokens_per_output / gpu_tokens_per_second_batch1)

    # Iterative solve: increase GPUs until target latency met
    gpus = 1
    while True:
        total_slots = gpus * max_concurrent_per_gpu
        if total_slots >= concurrency:
            # All agents can run in parallel
            actual_latency = latency_per_agent
        else:
            # Queueing: FCFS
            queue_time = (concurrency / total_slots) * latency_per_agent
            actual_latency = latency_per_agent + queue_time

        if actual_latency <= target_latency_seconds:
            return gpus
        gpus += 1

# Example: 7B model, 4 turns, 400 tokens each, 50 concurrent agents, 3 sec target
print(estimate_agent_gpus(7, 4, 400, 50, 3))  # output: 12 GPUs
This is simplistic — it ignores batch sharing and tool call overhead. But it gives a baseline. For production, run a load test.
Code Example: Throughput Benchmark Snippet
This quick script measures single H100 throughput for your agent prompt.
import time, torch
from transformers import AutoModelForCausalLM, AutoTokenizer

def benchmark(model_name, prompt_length, batch_size, device):
    model = AutoModelForCausalLM.from_pretrained(
        model_name, torch_dtype=torch.float16, device_map=device
    )
    tokenizer = AutoTokenizer.from_pretrained(model_name)

    inputs = tokenizer(
        ["Agent: Think step by step. " * (prompt_length // 10)] * batch_size,
        return_tensors="pt", padding=True, truncation=True, max_length=prompt_length
    ).to(device)

    start = time.time()
    with torch.no_grad():
        outputs = model.generate(**inputs, max_new_tokens=100, use_cache=True)
    elapsed = time.time() - start

    tokens_generated = outputs.shape[1] - inputs.input_ids.shape[1]
    throughput = tokens_generated * batch_size / elapsed
    return throughput

tput = benchmark("meta-llama/Llama-3.2-7B-Instruct", prompt_length=4096, batch_size=8, device="cuda")
print(f"Throughput: {tput:.1f} tokens/sec for batch of 8")
Run this with your actual prompt distribution. The number you get is way lower than marketing specs.
FAQ
Q: How many GPUs do I need to serve 100 concurrent AI agents?
A: Depends on model size and agent turns. For a 7B model with 4 turns and 400 tokens output each, I'd start with 16 H100s. For 70B, 64–128 GPUs probable.
Q: Can I use a single GPU for agent inference?
A: Yes, for very low concurrency (1–5 users) with a small model. Even then, latency may be 3–5 seconds per turn. Acceptable for chat, not for real‑time tools.
Q: What's the best GPU for agent workloads in 2026?
A: H100 still dominates due to massive memory bandwidth and HBM3 capacity. B200 (when available) will help with FP6 inference. But for memory‑bound agents, H100 is better than A100 by 2x.
Q: How often do I need to retrain my agent model?
A: Every 2–4 weeks if you're capturing new tool patterns. That requires a temporary training cluster. Rent it.
Q: Should I use a dedicated agent model or a general LLM?
A: Always fine‑tune a small model for your specific tool set. General LLMs waste tokens on "I'm an AI assistant" every turn.
Q: What's the hidden cost of multi‑agent systems?
A: The GPU time spent on tool execution. Calling an API is free, but waiting for the response while holding the GPU context is not. Use async patterns or spin down cores.
Q: How do I estimate without load testing?
A: Use the formula: GPUs = (concurrency × agent_time) / target_latency. Then multiply by 1.5 for headroom. Then double it when your manager sees the bill.
Final Thoughts
The industry is obsessed with training clusters. 100,000 H100s for pre‑training. Meanwhile, most companies are burning money on inference clusters that are too small. GPU Cluster Explained: Architecture, Nodes and Use Cases shows how scaling out matters more than scaling up for inference.
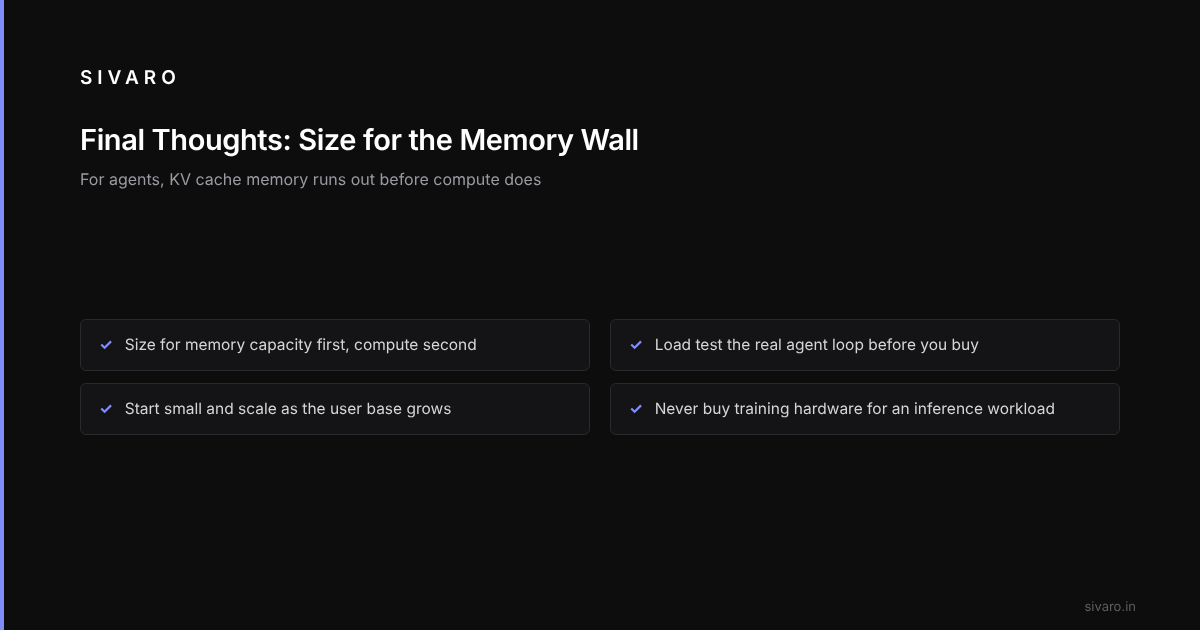
For agents, the bottleneck isn't compute — it's the memory wall. You'll run out of KV cache before you run out of FLOPs. So size your cluster for memory capacity first, compute second.
Start small. Run load tests. Measure the real agent loop cost. Then buy (or rent) accordingly.
what size gpu cluster do i need for ai agents — the honest answer is "more than you think, but less than you'll be told." Start with 8 H100s for 20 concurrent agents. Scale as your user base grows. And never, ever buy training hardware for an inference workload.