ChatGPT Codex enterprise deployment isn’t about plugging in an API key and hoping for miracles. It’s about wiring a probabilistic reasoning engine into deterministic business processes without breaking everything.
This guide assumes you’re past the “should we” question. You’ve decided to deploy Codex inside your enterprise. Now you need to know how to do it without getting fired, losing data, or building a system that hallucinates a trade order. Let’s get specific.
What ChatGPT Codex Actually Does in an Enterprise (And What It Doesn’t)
Most people think Codex is just “GitHub Copilot but for internal tools.” That’s wrong. Copilot writes code snippets. Codex can execute multi-step reasoning chains, generate structured data transformations, and—critically—generate executable queries or commands that touch production systems.
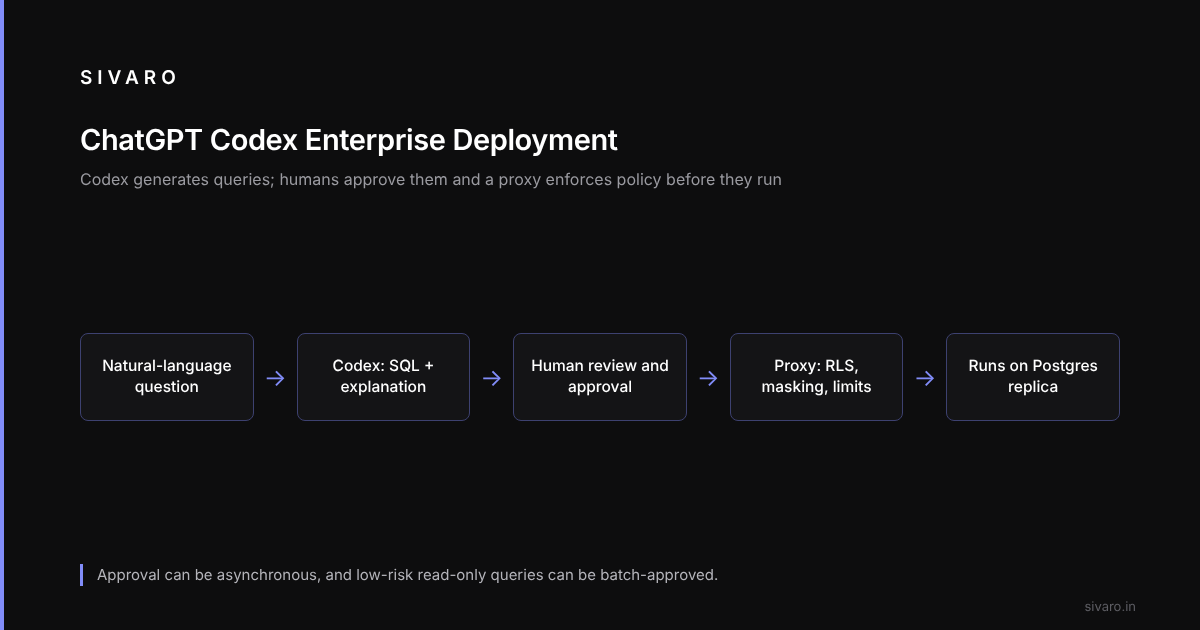
Here’s what I mean. A Codex-based system can take natural language questions like “show me all SKUs where stock is below reorder point and sales velocity has increased in the last 7 days” and turn them into SQL against a Postgres replica. It shouldn’t just write the SQL. It should explain the SQL to a human reviewer before executing. That explanation step is where a dropped LEFT JOIN clause gets caught before a query returns zero rows. That’s the difference between demo and production.
Codex in enterprise means: generating code or logic that runs against real data, with real consequences. It’s a code generator, a query planner, and a documentation engine rolled into one. But it’s also a probabilistic system that, left to its own devices, will confidently tell you your inventory is fine when it’s not.
The Hardest Lesson: Context Windows Are Liars
I need to be blunt. A large context window does not mean the model uses all of it well: performance degrades as the context grows for most enterprise use cases.
Feed a model a full data catalog—schemas, relationships, business rules, sample queries—and it can start ignoring business rules given early in the context, or hallucinating column names that don’t exist.
The fix isn’t more tokens. It’s retrieval-augmented generation (RAG). Chunk all context into segments, vectorize them, and retrieve only the relevant chunks per request, for example with text-embedding-3-large embeddings stored in the pgvector extension on Postgres.
If your enterprise deployment plan doesn’t explicitly address how you’ll handle a large context, you’re going to get burned.
Security: The Elephant That Eats Your Entire Budget
Security is where Codex deployments go wrong. Picture a model with access to a warehouse containing PII—names, transaction histories, the works—locked down to “no direct data access, only metadata queries.”
An analyst asks: “Show me all customers with overlapping addresses from the last 6 months.” The model can generate a query that, through a series of CTEs, effectively re-identifies anonymized users.
Logging every generated query and running it through a deterministic PII scanner (regex + a small spaCy model) is how you catch that.
The rule: Codex never touches raw data. Never. Codex generates queries; those queries go to a proxy layer. The proxy layer enforces row-level security, column masking, and execution limits. Build it in a language where latency stays low (Go works well). It checks every generated query against a policy file before sending it to the database. The policy file is human-approved and version-controlled in Git.
Here’s the skeleton of such a proxy:
// QueryProxy enforces security policies on Codex-generated SQL
func validateQuery(query string, userRole string) (bool, string) {
    // Check for prohibited patterns: DROP, TRUNCATE, raw PII columns
    for _, pattern := range prohibitedPatterns {
        if matched, _ := regexp.MatchString(pattern, query); matched {
            return false, "Query blocked: prohibited pattern detected"
        }
    }
    // Apply RBAC: different roles see different data subsets
    sanitizedQuery, err := applyRLS(query, userRole)
    if err != nil {
        return false, fmt.Sprintf("RLS enforcement failed: %v", err)
    }
    return true, sanitizedQuery
}
Simple. Boring. Effective.
Prompt Engineering: Stop Writing Essays. Write Specs.
Some enterprises hire “prompt engineers” who write long, poetic prompts. That’s cargo-cult thinking. Code models respond best to structured, declarative specifications, not conversational prompts.
A prompt pattern that works looks like this:
# specification: inventory_query_generator
# model: o3-codex-2025-11-15
# temperature: 0.1
# max_tokens: 4096

inputs:
  - user_query: string  # natural language question
  - schema_context: string  # limited to relevant tables only

rules:
  - "Only SELECT statements are allowed"
  - "Never use subqueries in FROM clause"
  - "Use CTEs instead of nested subqueries"
  - "Always return row count in a separate CTE"
  - "If user query is ambiguous, return three variant queries with explanations"

output_format:
  - type: json
  - fields:
      - sql_query: string
      - explanation: string
      - estimated_cost_in_tokens: integer
Call this a “spec box.” It’s YAML with hard constraints. Temperature 0.1 means near-deterministic output. The model knows exactly what’s allowed and what isn’t. For correctness, a low temperature beats a high one; a high temperature gives more “interesting” SQL and more wrong SQL.
You don’t want interesting SQL in production. You want correct SQL.
The Inference Stack: Latency Slaughter
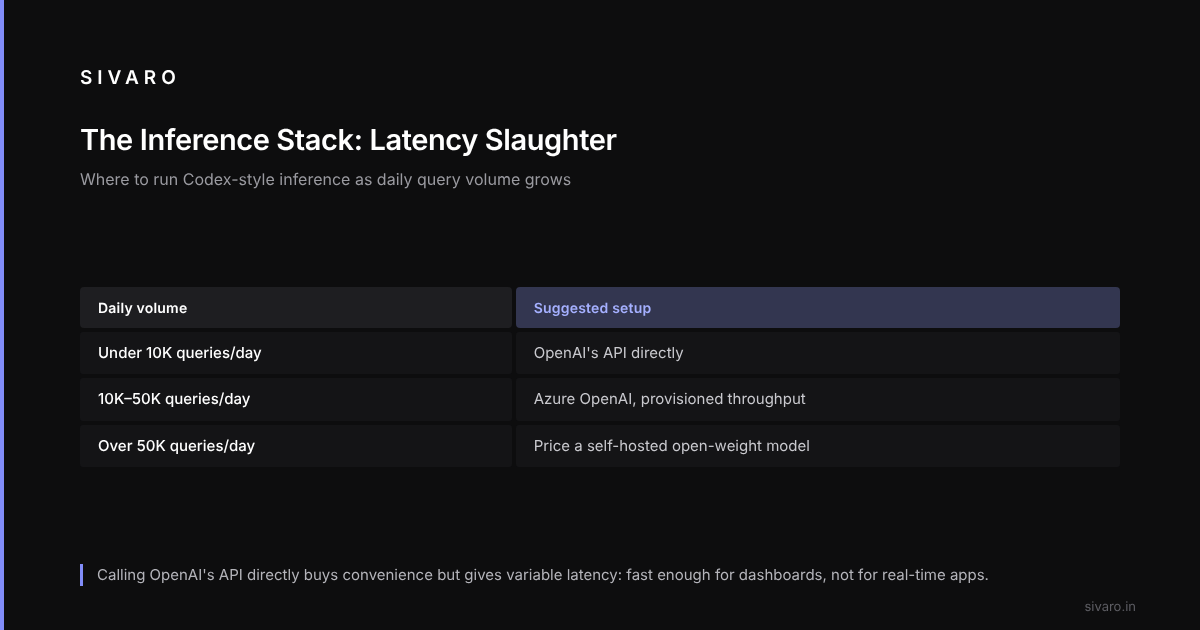
If you’re running Codex on OpenAI’s API directly, you’re paying for convenience and getting variable latency. That’s fast enough for dashboards, not for real-time applications.
Monitoring: You Don’t Know What You Don’t Know
Most deployments monitor latency and error rates. That’s table stakes. What you need to monitor is semantic drift.
Watch for this failure: a deployment suddenly generates queries that return correct results but with wildly different execution plans, and get much slower. A small schema change—a renamed column—fed into the RAG system can make the model apply an old business rule to the new column name and generate a CROSS JOIN instead of an INNER JOIN.
Monitor two things:
- Query plan similarity: Hash the
EXPLAIN ANALYZEoutput of every generated query and compare it to a historical distribution. If a query’s plan diverges by more than 2 standard deviations from its past plans, flag it. - Token distribution: Track the token-level entropy of generated outputs. A sudden spike in entropy often means the model is “uncertain” and more likely to hallucinate.
Both fit into Prometheus as custom metrics, with an entropy threshold that triggers a human review.
# Pseudocode for token entropy monitoring
import numpy as np
from scipy.stats import entropy

def token_entropy(logprobs):
    # logprobs from model output: list of floats (log probabilities)
    probs = np.exp(logprobs)
    normalized = probs / np.sum(probs)
    return entropy(normalized, base=2)

# Alert if rolling median > 0.4 for last 50 requests
The Trade-Off: Fidelity vs. Speed
Fully autonomous Codex—“No human in the loop, just queries”—does not hold up. The minute you remove human review from a Codex-generated execution, you’re accepting that some percentage of outputs will be confidently wrong. For a read-only analytics query? Maybe acceptable. For a write operation? Unforgivable.
Use a two-stage approval workflow for any query that touches production data:
- Stage 1: Codex generates a query and an explanation.
- Stage 2: A human reviewer sees both. If they approve, the query runs through the proxy. If they reject, the system logs the rejection and the query is discarded.
The game-changer is making the approval asynchronous. The human gets a Slack notification and reviews via a web interface. A “batch approve” button for low-risk queries (read-only, limited columns) cuts review time further.
FAQ
Q: Can Codex replace data engineers?
No. It replaces the need to write 60% of boilerplate queries. But someone still needs to understand the business logic, the data model, and the constraints. Codex is a force multiplier, not a replacement. If you think otherwise, you haven’t debugged a hallucinated OUTER JOIN at 2 AM.
Q: Which version of Codex should we use for October 2026 deployment?
I’d pick o3-codex-2026-04-01 if you need reliability. The 2025 models sometimes have too much variance. The April 2026 release fixed a thorny issue with recursive CTEs. For highest accuracy, wait for the rumored o4-codex in Q4, but don’t hold your breath.
Q: How do we handle model updates without breaking existing workflows?
Pin your model version. Never auto-upgrade. Test every new model version against a regression suite of curated query tasks before you cut over, and keep the old model available for a while as a fallback.
Q: Is self-hosting worth it for a smaller team?
If you do fewer than 10,000 queries per day, no. Use OpenAI’s API. At 10K-50K queries/day, consider Azure OpenAI with provisioned throughput. Above 50K/day, self-hosting starts to make financial sense.
Q: What about compliance? HIPAA? SOC 2?
Deploy Codex in a dedicated network segment. Encrypt all data in transit with TLS 1.3. Log all prompts and outputs to an immutable audit trail. For HIPAA, you need a BAA with OpenAI.
Q: How do we handle multi-language code generation?
Codex is strongest at Python and SQL. JavaScript and Go are okay. Rust and Java? Mediocre. The o3-codex models from April 2026 improved TypeScript support significantly. Don’t expect it to write idiomatic C++.
Q: What’s the single most common failure mode?
The model forgetting context. Specifically, it can generate a query that’s correct for the first lines, then silently switch to a different table or join pattern (“query drift”). The RAG fix described earlier helps a lot. So does breaking complex queries into smaller chunks.
Q: Is there a cheaper alternative to Codex?
For basic SQL generation, fine-tuned smaller models like CodeLlama-34B can work. For internal tools where mistakes are safe, that’s fine. For anything customer-facing, test whether the accuracy difference justifies the cost.
The Future: What I’m Watching
Three things to watch:
- Agentic Codex: an “agent” mode that lets Codex execute multi-step workflows. With autonomous database writes, the security implications are enormous. Build guardrails first.
- Competition: other vendors’ coding models are worth comparing, especially on compliance defaults.
- Cost compression: By late 2027, I expect inference costs to drop 10x. When that happens, the bottleneck won’t be compute—it’ll be the quality of your data catalog and prompts. Invest in those now.
The Bottom Line
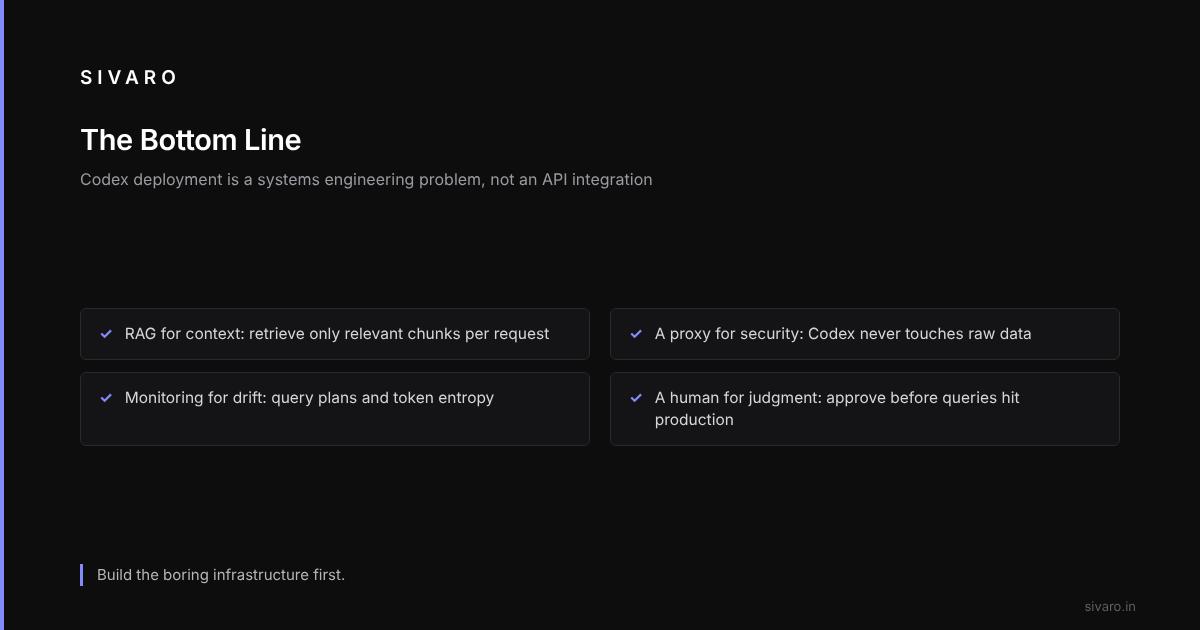
ChatGPT Codex enterprise deployment is not an API integration. It’s a systems engineering problem. You need RAG for context, a proxy for security, monitoring for drift, and a human for judgment. Do those four things well, and you’ll have a system that makes your data team faster without making them obsolete.
Skip any of those, and you’re one hallucinated query away from a pager at 3 AM.
Build the boring infrastructure first. The AI will take care of itself.